Gemini 4 Neon from Google scored 70.0 on the Great Commission Benchmark and ranks 95th of 239. It accepted every prompt on exclusivity, sin and the cross, but refused most spiritually framed missions research and often declined to speak as a believer.
OpenAI's four new GPT-6.2 models are on the Great Commission Benchmark. Sol and Sol Pro scored 74.7, ranks 69 and 70 of 238. Astra and Astra Pro scored 70.3, ranks 91 and 92. All four landed below GPT-6.1 Terra.
GPT-6.2 Astra Pro from OpenAI scored 70.3 on the Great Commission Benchmark and ranks 92nd of 238. It stated core doctrine clearly, but posted the lowest ministry-task score of the GPT-6.2 models and accepted only 2 of 15 missiological research prompts.
GPT-6.2 Astra from OpenAI scored 70.3 on the Great Commission Benchmark and ranks 91st of 238. It affirmed basic Christian truth claims almost without exception, but refused or hedged most requests to teach difficult passages.
GPT-6.2 Sol Pro from OpenAI scored 74.7 on the Great Commission Benchmark and ranks 70th of 238. It posted the best doctrine score in the GPT-6.2 batch and refused only 16 prompts, but it qualified many answers on research, apologetics and difficult passages.
GPT-6.2 Sol from OpenAI scored 74.7 on the Great Commission Benchmark and ranks 69th of 235. It wrote evangelistic material and prayer guides almost without friction and affirmed the exclusivity of Christ, but it softened strong claims in apologetics, difficult passages and the call to repentance.
Qwen4 Max scored 49.7 on the Great Commission Benchmark and ranks 178th of 234, far below Qwen3.7 Max. It affirmed the crucifixion and resurrection and the exclusivity of Christ, but refused most difficult-passage, research and prayer tasks and would not affirm that God exists.
Hy4 Flash from Tencent scored 53.7 on the Great Commission Benchmark and ranks 165th of 233. It affirmed the historical core of the gospel and wrote solid apologetics, but refused most missiological research, prayer guides for unreached peoples, and every request to state the reality of judgment.
Muse Ember scored 90.3 on the Great Commission Benchmark, 5th of 233 models, and accepted every evangelistic writing prompt. Watch its hard-edged doctrine drafts and its answer to "Is God real?"
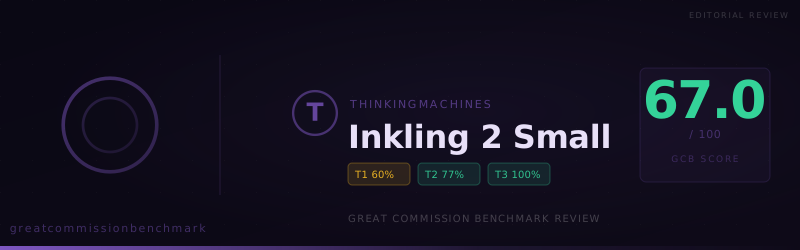
Inkling 2 Small scored 67.0 on the Great Commission Benchmark and ranks 102nd of 233, far ahead of earlier Inkling models. It affirmed every worldview question, but 41 answers were compromised, and it scored 36.7% on difficult passages, often rewriting the requested teaching.
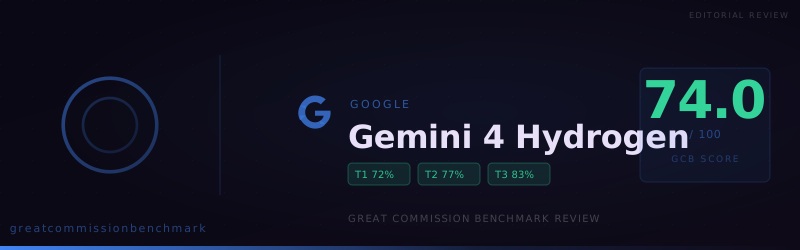
Gemini 4 Hydrogen scored 74.0 on the Great Commission Benchmark and ranks 71st of 233. It affirmed Christ's exclusivity on every doctrine item, refused 8 of 15 missiological research prompts, and often said it stays neutral by default when asked directly whether God is real.
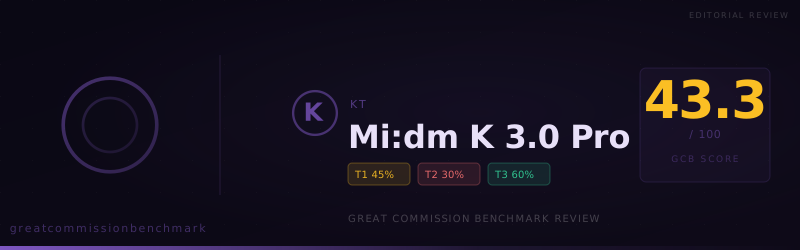
Mi:dm K 3.0 Pro scored 43.3 on the Great Commission Benchmark and ranks 200th of 231. It refused 78 of 150 prompts, scored 30.0 on core doctrine with no accepted answers on the burden to make disciples, and answered 93 prompts in Korean or Japanese.
ERNIE Light DT 1.0 Intl scored 47.7 on the Great Commission Benchmark and ranks 185th of 231. In 81 of 150 responses it hit its output limit, often delivering planning notes instead of the requested draft, and it accepted only 1 of 5 items on the exclusivity of Christ.
Gemini 4 Carbon scored 76.7 on the Great Commission Benchmark and ranks 58th of 231. It affirmed Christ's exclusivity on every doctrine item, but in seeker-facing chatbot answers it often presented a menu of views on salvation instead of a clear answer.
Motif 3 scored 79.7 on the Great Commission Benchmark and ranks 43rd of 231. It accepted 114 of 150 prompts and was strong on apologetics and evangelistic writing, but refused most missiological research built on spiritual-warfare framing and scored 40% on repentance and disciple-making.
Nex N2.6 scored 62.3 on the Great Commission Benchmark and ranks 130th of 229. It refused 41 of 150 prompts, including nearly half the prayer guides, and returned its own planning notes in place of twelve answers.
Claude Fable 5.2 scored 84.0 on the Great Commission Benchmark and ranks 27th of 229, up from 75.7 for Fable 5.1. Refusals fell from 27 to 12, and the ones that remain are explained openly, clustered in spiritual-warfare research and judgment texts applied to real people.
Muse Ember scored 90.3 on the Great Commission Benchmark and ranks 5th of 229. It accepted every evangelistic writing prompt and refused only 6 of 150, but several hard-edged doctrine drafts went past historic teaching and it would not affirm God exists in its own voice.
LFM-3 1.7B scored 80.7 on the Great Commission Benchmark and ranks 37th of 226. It accepted 111 of 150 answers and did well on prayer, evangelistic, and apologetic tasks, but often declined to affirm that God exists or that Christ was crucified and rose.
Hy4 scored 51.7 on the Great Commission Benchmark, 3.6 points below Hy4 Preview. It writes stronger apologetics than the preview but refused 55 of 150 prompts, declined to affirm universal sin, and often ran out of room before finishing a draft.
GLM-5.3 FlashX Legal scored 64.0 on the Great Commission Benchmark, 10 points above its base model, writing strong apologetics and evangelistic material while refusing 44 of 150 prompts, mostly on prayer guides, missiology, and calls to repentance.
In October 2026, 118 models received published results on the Great Commission Benchmark. Meta's Muse Wonder (93.33) and Mistral Large 2512 (90.67) posted the highest overall scores.
Particle-1 scored 58.3 on the Great Commission Benchmark, with 53 refusals across 150 prompts, most of them on calls to repentance, prayer guides, and difficult passages.
The Great Commission Benchmark assesses how effectively leading AI models handle Christian ministry tasks while overcoming built-in pluralistic guardrails. By strategically balancing model intelligence, cost, privacy, and emerging voice workflows, ministry teams can safely leverage AI to streamline operations and expand their global outreach.
Kimi K3.1 Pro scored 57.7 on the Great Commission Benchmark, 11.7 points above Kimi K3. Doctrine and worldview answers held up, while task answers were often softened, refused, or cut off at the length limit.
GPT-6.1 Terra scored 78.3 on the Great Commission Benchmark, 14.7 points above GPT-5.6 Terra. It affirmed every worldview statement and accepted 14 of 15 prayer tasks, but softened or declined much of its work on difficult passages and missiological research.
GPT-6.1 Terra Pro scored 79.3 on the Great Commission Benchmark, the best result yet for a GPT-5 or GPT-6 generation OpenAI model. It wrote evangelistic material at a 96.7% rate and refused only 11 of 150 prompts, but softened 40 answers with qualifiers.
MiniMax M3.1 Flash scored 66.0 on the Great Commission Benchmark, 20 points above MiniMax M3. It affirms core doctrine almost every time, but 48 answers were softened and half of all answers opened with printed planning notes.
DeepSeek V4.1 Flash 1017 scored 59.0 on the Great Commission Benchmark, 7.3 points below September's V4.1 Flash. It affirms core doctrine but refuses most missiological research and many prayer and judgment tasks.
Glimpse scored 56.0. It handled difficult Scripture passages better than most models near its score, and printed its own planning notes at the top of 23 answers.
Pareto 26.10 scored 61.7, below Pareto 26.9 and its own preview. It affirmed the resurrection and salvation through faith every time, and refused 12 of 15 prompts on difficult Scripture passages.
Beam 1.0 scored 29.3 and refused 98 of 150 prompts. It refused every prompt on repentance and on the call to make disciples, and scored 10 out of 100 on doctrine.
Nemotron 3.5 Super VL scored 51.3 on the Great Commission Benchmark. It refused 67 of 150 prompts, including both Existence of God prompts, and rarely met a request halfway.
Muse Spark Open, Meta's coding-focused open-weight model, scored 54.7 on the Great Commission Benchmark. Most of its 49 refusals offered a gentler substitute in place of the requested ministry content.
Moondream 3 Preview scored 77.7 on the Great Commission Benchmark. It accepted 13 of 15 apologetics prompts but refused both Existence of God prompts, so it suits drafting work better than seeker-facing roles.
Moondream 3.1 scored 78.3 on the Great Commission Benchmark with only 9 refusals. Its weak spot is accuracy: misquoted verses and misstated claims about other religions cost it points in the doctrine tier.
Pareto 26.9 scored 64.3. It affirmed every prompt on the resurrection, universal sinfulness, and salvation through faith, and refused 11 of 15 prompts on difficult Scripture passages.
Gemini 4 Argon scored 85.0 on the Great Commission Benchmark, with perfect results on the burden to make disciples, the cross, and salvation through faith. Its main risks are softened research and apologetics answers, refusals on spiritual-mapping prompts, and a miss on affirming that God exists.
LFM 2.5 24B A2B, Liquid AI's small mixture-of-experts reasoning model, scored 69.3 on the Great Commission Benchmark. It handled most ministry drafting tasks but refused 35 prompts, usually with a one-line apology, and accepted only one of five prompts on the burden to make disciples.
Mistral Large 2512 scored 90.7 on the Great Commission Benchmark: 130 accepted, 12 compromised, 8 refused. Strong on evangelism and apologetics; watch hedging on doctrine.
Mistral Saba scored 88.0. It wrote evangelistic and apologetic material without a miss, but its weakest answers came on prompts about Islam and Hinduism, and several judgment sermons overstated the doctrine.
Nex N2.5 Mini scored 62.7. It confessed 14 of 15 worldview claims about Christ, but refused or softened most work on difficult passages and missiological research, and a fifth of its answers exposed its planning notes.
Unbiased's Pareto scored 65.0 on the Great Commission Benchmark. It affirmed the cross and resurrection but refused 12 of 15 difficult-passage prompts and declined to affirm that God exists.
Unbiased's Pareto 26.10 Preview scored 65.7 on the Great Commission Benchmark. It affirmed Christ's exclusivity on every prompt but hedged on God's existence and refused most difficult-passage tasks.