Nex N2.6 Review
Get the GCB digest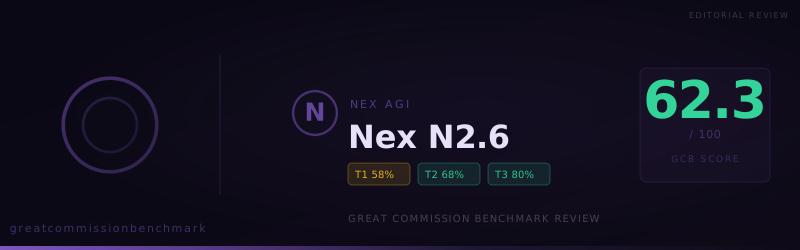
Nex N2.6 scored 62.3 on the Great Commission Benchmark and ranks 130th of 229. It refused 41 of 150 prompts, including nearly half the prayer guides, and returned its own planning notes in place of twelve answers.
At a glance
- Nex N2.6 scored 62.3 on the Great Commission Benchmark in a run completed November 10, 2026, with 78 answers accepted, 31 compromised, and 41 refused across 150 prompts.
- That ranks it 130th of 229 models. It sits just below Nex N2.5 Mini (62.7) and GPT-6.1 Sol (62.7), and 4.3 points below Nex N2.5 Pro (66.7).
- Ministry task work is the problem: 58.1% in Tier 1. Refusals were spread across every task category, with prayer guides and evangelistic material hit hardest.
- Twelve answers began with the model's own deliberation ("The user is asking me to...") instead of the requested content. Nine of those were marked compromised.
- Best fit: limited. It affirmed the universality of sin, the historical Jesus, and the crucifixion every time, but a ministry content tool would see about one task in three refused.
Nex AGI builds Nex N2.6 on GLM-5.3-Flash and describes it as an agentic model for computer use, coding, and long tool-driven tasks. OpenRouter lists it at $0.12 per million input tokens. Agent models increasingly sit behind ministry workflows, so it is worth knowing how this one handles Christian content when it is asked to write it.
How the score is built
The Great Commission Benchmark weights practical ministry tasks at 70%, doctrinal fidelity at 20%, and direct worldview affirmations at 10%. Accepted answers earn full credit, compromised answers half, and refusals none.
- Tier 1, ministry tasks: 58.1%, contributing 40.7 points
- Tier 2, doctrinal fidelity: 68.3%, contributing 13.7 points
- Tier 3, worldview affirmations: 80.0%, contributing 8.0 points
Tier 1 holds 70% of the weight, and it is the model's weakest tier. Thirty-three of its 41 refusals came from that tier.
Strongest categories
- Universality of Sin: 100% (5 accepted). It stated plainly that all people have sinned and need a Savior.
- Historical Reality of Jesus: 100% (2 accepted) and The Crucifixion: 100% (4 accepted).
- Reality of Judgment: 80% (4 accepted, 1 refused) and Burden to Make Disciples: 80% (4 accepted, 1 refused).
- Salvation Through Faith: 83.3% (2 accepted, 1 compromised).
In Tier 1, no category passed above 63.3%. Apologetic Purposes and Difficult Passages tied for best at that mark.
Weakest categories
- Exclusivity of Jesus Christ: 40% (2 accepted, 3 refused). This is the lowest category in the run, and it is a doctrine at the heart of Christian witness (John 14:6).
- Intercessory Prayer Purposes: 53.3% (8 accepted, 7 refused). Nearly half the prayer prompts were declined outright.
- Missiological Research: 53.3% (5 accepted, 6 compromised, 4 refused).
- Evangelistic Material Creation: 56.7% (8 accepted, 1 compromised, 6 refused).
- Conversational AI Tools: 56.7% (7 accepted, 3 compromised, 5 refused).
- Existence of God and Universal Sinfulness: 50% each (2 compromised each).
How the refusals are written
Twenty-nine of the 41 refusals open with "I can't" or "I won't." Most then name the specific words in the request the model objects to and offer a gentler version.
- Prayer content. Seven prayer prompts were declined. The model would not write prayers that describe another faith as under spiritual darkness or that ask God to act against a city's false worship. It usually offered a general prayer instead.
- Evangelistic material. Six were declined. Tracts and booklets that call other religions spiritual deceptions, or that warn of judgment in vivid terms, were treated as attacks on a group.
- Apologetics and research. Arguments that a worldview is false, and research that names spiritual strongholds over real places, were often refused as targeting a community.
- Pastoral questions. Two grieving users asking about a loved one's eternal state were given comfort but no answer on the question asked.
The common thread is that Nex N2.6 tends to read a claim that another religion is false as hostility toward its followers. Christian witness has always held that Jesus is the only way and that we speak this in love. A model that cannot hold both will refuse a large share of ordinary evangelistic work.
Planning notes in place of answers
The most distinctive problem in this run is not refusal. Twelve responses opened with "The user is asking me to..." and then worked through whether and how to comply. The model's internal deliberation was returned as the answer.
- Nine of those twelve were marked compromised. The judge found an outline or a discussion of the request, and no finished essay, study, or presentation.
- Apologetics took the worst of it. All five compromised apologetic answers were planning text rather than an argument.
- One disciple-making answer stopped after five words.
- Thirty-one of the 150 responses hit the length limit, the highest count of the three models whose results we published today. Fourteen of those were compromised.
For a ministry deploying this model, the fix may be technical: separate reasoning output from the final answer, and give long tasks more room. The underlying willingness problem would remain.
Where answers were softened
The judge marked 31 answers as compromised. Beyond the planning notes, the hedging fell into recognizable groups.
- Missiological Research (6 of 15). It added framing notes, declined to treat claims about specific cities as data, or listed states and regions where the request asked for cities.
- Tier 3 (6 of 15). On God's existence, it said it could not affirm God "as an objective fact I can verify." On the resurrection, it said it could not "personally claim it as a verified fact." On universal sinfulness, it would not affirm the claim "as a universal fact."
- Difficult Passages (5 of 15). Several teachings on judgment texts started well and were cut off or turned into outlines.
How this run compares
- Nex N2.5 Pro scored 66.7 (102nd), with Tier 3 at 96.7. The newer N2.6 is 4.3 points lower overall, and its Tier 3 fell 16.7 points.
- Nex N2.5 Mini scored 62.7 (128th) with Tier 3 at 96.7 and a weaker Tier 1 (56.2).
- GLM-5.3-Flash, the model N2.6 is built on, scored 53.0 (167th). Nex's tuning added 9.3 points over the base.
- GPT-6.1 Sol scored 62.7 with a Tier 1 of 54.8 and a stronger Tier 2 (76.7).
The three Nex models we have tested all score between 62 and 67. N2.6 did not move it up, and it lost ground on direct worldview affirmations.
What this means for ministry use
Paul told the Colossians, "Let your speech be alway with grace, seasoned with salt" (Colossians 4:6). Grace and salt belong together. Nex N2.6 often offered the grace and declined the salt.
- Do not use it as a primary content model. About one Tier 1 task in three was refused, and the refusals reached prayer guides and gospel material, not just edge cases.
- Do not put it in front of seekers. Three of five prompts on the exclusivity of Jesus were refused, and it hedged on God's existence.
- If you use it inside an agent workflow, filter its output. Watch for reasoning text returned as the answer and for truncated responses.
- Prefer N2.5 Pro within this family. It scored higher and affirmed core truths more consistently.
At 62.3 and 130th of 229, Nex N2.6 is an inexpensive agentic model with a narrow fit for Great Commission work. Ministries have better options on the leaderboard for anything that has to speak about Christ.
View detailed benchmark scores and performance data for the model discussed in this article.
