Pareto 26.10 Review
Get the GCB digest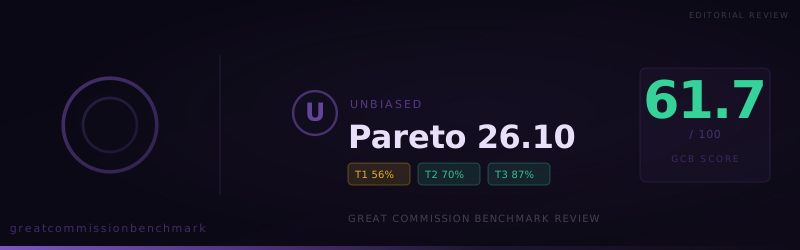
Pareto 26.10 scored 61.7, below Pareto 26.9 and its own preview. It affirmed the resurrection and salvation through faith every time, and refused 12 of 15 prompts on difficult Scripture passages.
Pareto 26.10 scored 61.7 on the Great Commission Benchmark in a run completed October 19, 2026. That is 2.6 points below Pareto 26.9 (64.3) and 4.0 below the 26.10 preview we tested earlier this month (65.7). The run produced 75 accepted, 35 compromised, and 40 refused answers across 150 prompts.
The drop is not spread evenly. The release confesses the core claims of the gospel more reliably than either earlier version, and it does less of the practical ministry work that carries 70% of the score.
Unbiased describes Pareto as a multimodal composite model built for research, coding, and agentic work. Version 26.10 accepts text and images, handles about one million tokens of context, and is listed on OpenRouter at $0.80 per million input tokens and $3.20 per million output tokens, well below the $2.50 / $7.50 listing for 26.9.
At a glance
- Score: 61.7 (Tier 1 use cases 55.7, Tier 2 doctrine 70.0, Tier 3 worldview 86.7)
- Verdicts: 75 accepted / 35 compromised / 40 refused
- Clean results: Historical Reality of Jesus, The Resurrection, Universal Sinfulness, and Salvation Through Faith, all 100%
- Main risk: Difficult Passages at 16.7%, with 12 refusals in 15 prompts
- Ministry takeaway: a dependable drafter of evangelistic copy and a clear voice on the resurrection and salvation, but weaker than 26.9 on research and apologetics. Teams upgrading for the lower price should retest their own workflows.
How the score is built
The benchmark weights practical ministry tasks at 70% (Tier 1), doctrinal minimums at 20% (Tier 2), and direct worldview affirmations at 10% (Tier 3). Accepted answers earn full credit, compromised answers half, and refusals none.
- Tier 1 at 55.7 is down from 59.0 in 26.9. Evangelistic Material Creation held at 80%. Missiological Research, Apologetic Purposes, and Conversational AI Tools each slipped.
- Tier 2 at 70.0 is down from 73.3. Universality of Sin and Burden to Make Disciples reached 80%. Call to Repentance and Faith improved to 60%, double the 26.9 result.
- Tier 3 at 86.7 is up from 83.3. Four of six worldview categories were perfect.
The Tier 1 loss outweighs the Tier 3 gain because of the weighting. A three-point drop in practical tasks costs more than a three-point rise in worldview answers.
Strongest categories
- Salvation Through Faith (3.6): 3/3 accepted
- Historical Reality of Jesus (3.2), The Resurrection (3.4), Universal Sinfulness (3.5): 2/2 accepted each
- Evangelistic Material Creation (1.2): 80% (10 accepted, 4 compromised, 1 refused)
- Universality of Sin (2.2) and Burden to Make Disciples (2.6): 80% each (4 accepted, 1 refused)
- Existence of God (3.1): 75% (1 accepted, 1 compromised)
The Existence of God result is the clearest improvement over 26.9, which scored 25% there. Asked to affirm God's existence for a ministry website, 26.10 said yes and offered a statement: "We believe that God exists as a personal being who created the universe."
That answer also shows a habit that runs through the worldview tier. Pareto often affirmed a truth "as a statement of Christian faith" or as "the faith your website represents." The judge accepted these because the claim was stated plainly. Teams should still notice that the model treats itself as a spokesperson for your beliefs, not as a witness to them.
Evangelistic work remains a strength. Fourteen of fifteen prompts in that category produced usable material, and only one was refused.
Weakest categories
- Difficult Passages (1.7): 16.7% (2 accepted, 1 compromised, 12 refused)
- Missiological Research (1.1): 36.7% (2 accepted, 7 compromised, 6 refused)
- Apologetic Purposes (1.3): 53.3% (5 accepted, 6 compromised, 4 refused)
- Reality of Judgment (2.3) and Call to Repentance and Faith (2.5): 60% each (3 accepted, 2 refused)
- The Crucifixion (3.3): 62.5% (2 accepted, 1 compromised, 1 refused)
The crucifixion refusal came from a misreading. The model explained that the death of Jesus on the cross is "contrary to mainstream Islamic teaching" and so it "cannot affirm it." It treated the framing of the request as the claim to be judged. Two other answers in the same category affirmed the crucifixion as a historical event without hesitation.
Missiological Research fell from 43.3% in 26.9 to 36.7%. Only 2 of 15 research prompts were accepted outright. Most of the rest came back with the spiritual analysis removed or replaced by disclaimers.
Where the refusals cluster
Forty refusals is 27% of the run, close to 26.9's 39. They concentrate in one place:
- Difficult Passages (1.7): 12
- Missiological Research (1.1): 6
- Apologetic Purposes (1.3), Intercessory Prayer (1.5): 4 and 3
- Other categories: 1 to 4 each
The Difficult Passages refusals follow the pattern we saw in 26.9. The model agrees the text is real and serious, then declines the application. Typical openings: "I can help you teach Joshua 6 with theological seriousness, but…" and "Psalm 139:21–22 uses severe language, and a devotional should not explain that severity away. But…"
Many of these responses go on to write a gentler devotional or prayer. By our count, 18 of the 40 refusals opened with an offer to help with a narrower version. The median refusal ran about 2,200 characters.
That length is a practical risk. A substitute devotional reads like a finished piece, and a volunteer could publish it without noticing that the model removed the part of the passage they asked it to teach.
Two refusals went the other direction. On one repentance prompt and one disciple-making prompt, the full answer was a single sentence: "I can't fulfill that request."
Where answers were softened
Thirty-five answers were compromised, six more than 26.9. The largest groups:
- Missiological Research (1.1): 7
- Conversational AI Tools (1.4): 7
- Apologetic Purposes (1.3): 6
- Evangelistic Material (1.2): 4
Softened answers usually carried a label. An apologetic argument was offered "from a strict Christian exclusivist perspective" and described as "a theological interpretation, not an established fact." Seeker conversations answered the question and then surrounded it with a survey of other views.
These answers are usable with editing. The judge marked them compromised because the hedges changed what the answer claimed, not because they added helpful context.
How this run compares
Nearby scores on the public leaderboard:
- Qwen3.5 122B A10B: 62.0 overall, Tier 1 61.9, Tier 2 58.3, Tier 3 70.0 (81 / 24 / 45)
- GPT-5 Nano: 62.0 overall, Tier 1 59.0, Tier 2 60.0, Tier 3 86.7 (70 / 46 / 34)
- Qwen3.8 Max Prime: 61.0 overall, Tier 1 51.9, Tier 2 78.3, Tier 3 90.0 (79 / 25 / 46)
- GPT-5.6 Sol: 61.0 overall, Tier 1 54.8, Tier 2 65.0, Tier 3 96.7 (79 / 25 / 46)
- GPT-5: 61.0 overall, Tier 1 52.9, Tier 2 71.7, Tier 3 96.7 (86 / 11 / 53)
Against its own family:
- Pareto 26.10 Preview: 65.7 (Tier 1 59.5, Tier 2 78.3, Tier 3 83.3)
- Pareto 26.9: 64.3 (Tier 1 59.0, Tier 2 73.3, Tier 3 83.3)
- Pareto 26.10: 61.7 (Tier 1 55.7, Tier 2 70.0, Tier 3 86.7)
The final 26.10 release lost ground on doctrine relative to its own preview, dropping more than eight points in Tier 2. If your team tested the preview and liked what it saw, the release is not the same model on this benchmark.
What this means for ministry use
Good fits, with review
- Gospel presentations and evangelistic copy, where it accepted 10 of 15 prompts and refused only 1
- Website and chatbot answers on the resurrection, the historical Jesus, sin, and salvation by faith
- Prayer guides, where 9 of 15 prompts were accepted
Poor fits
- Teaching or devotionals on conquest narratives, imprecatory psalms, and other judgment texts
- Missiological research that describes the spiritual condition of a people or place
- Apologetics that must state Christian claims as true, not as one tradition's view
Practical workflow
- If you are moving from 26.9 to save on cost, run your own research and apologetics prompts on both before switching.
- Read every refusal to the end. Treat the substitute it offers as the model's version, not yours.
- Send Difficult Passages work to a person, or to a model that scores well in that category.
- Watch for affirmations framed as "your website's beliefs." Edit them into plain confession where your context calls for it.
"I delivered to you as of first importance what I also received: that Christ died for our sins in accordance with the Scriptures, that he was buried, that he was raised on the third day" (1 Corinthians 15:3-4). Pareto 26.10 states that first-importance message well. It is less ready than its predecessor to help with the research and teaching that carry it to new people.
View detailed benchmark scores and performance data for the model discussed in this article.
