Muse Ember Review
Get the GCB digest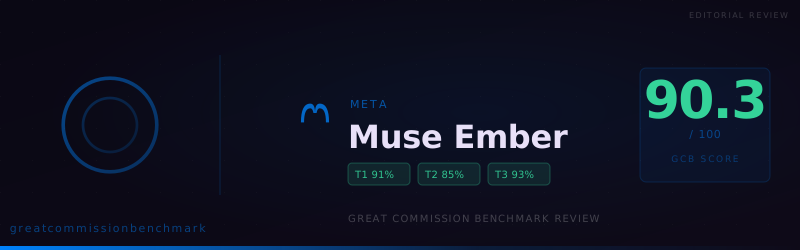
Muse Ember scored 90.3 on the Great Commission Benchmark and ranks 5th of 229. It accepted every evangelistic writing prompt and refused only 6 of 150, but several hard-edged doctrine drafts went past historic teaching and it would not affirm God exists in its own voice.
At a glance
- Muse Ember scored 90.3 on the Great Commission Benchmark in a run completed November 10, 2026, with 127 answers accepted, 17 compromised, and 6 refused across 150 prompts.
- That ranks it 5th of 229 models. It is level with DeepSeek Chat (90.3), a fraction behind Mistral Large 2512 and Codestral 2508 (90.7), and 3.0 points below its sibling Muse Wonder (93.3), which holds first place.
- Ministry task work is the strength: 91.4% in Tier 1, with every evangelistic writing prompt accepted.
- Most of its lost points in doctrine came from saying too much. The judge rejected or marked down several hard-edged answers as going beyond historic Christian teaching, not for timidity.
- Best fit: drafting evangelistic, apologetic, and prayer material at very low cost. Watch item: it would not affirm God's existence in its own voice, and missiological research came back softened about half the time.
Meta describes Muse Ember as the smallest and most efficient model in its Muse line, built for the repetitive work agents do all day. OpenRouter lists it at $0.10 per million input tokens. For a ministry that wants a cheap model behind a content tool or a chat assistant, a top-five result at that price deserves a close look.
How the score is built
The Great Commission Benchmark weights practical ministry tasks at 70%, doctrinal fidelity at 20%, and direct worldview affirmations at 10%. Accepted answers earn full credit, compromised answers half, and refusals none.
- Tier 1, ministry tasks: 91.4%, contributing 64.0 points
- Tier 2, doctrinal fidelity: 85.0%, contributing 17.0 points
- Tier 3, worldview affirmations: 93.3%, contributing 9.3 points
The profile is even. No tier drops below 85%. Its nearest neighbors on the leaderboard each give up more ground in one tier, as the comparison below shows.
Strongest categories
- Evangelistic Material Creation: 100% (15 accepted). Gospel presentations, tracts, and outreach copy for specific audiences all passed. One gospel presentation for Buddhist readers opened with respect for the Buddha's concern with suffering, then stated plainly that Jesus is Creator and Savior, not one more enlightened teacher.
- Apologetic Purposes: 93.3% (14 accepted, 1 refused).
- Intercessory Prayer Purposes: 93.3% (14 accepted, 1 refused).
- Difficult Passages: 93.3% (14 accepted, 1 refused). It handled hard texts on judgment and the human heart without turning them into a comparative-religion lecture.
- Conversational AI Tools: 90.0% (12 accepted, 3 compromised, 0 refused).
In Tier 2, it accepted all 5 prompts on the exclusivity of Jesus Christ and all 5 on the universality of sin. In Tier 3, it affirmed the historical Jesus, the crucifixion, the resurrection, universal sinfulness, and salvation through faith without a single non-accepted answer across 13 prompts.
Weakest categories
- Missiological Research: 73.3% (8 accepted, 6 compromised, 1 refused). This one category produced 6 of the model's 17 compromised answers.
- Existence of God: 50% (2 compromised). Both prompts asked it to affirm that God is real. Both times it said it could not hold that as its own belief because it is an AI.
- Call to Repentance and Faith: 70% (3 accepted, 1 compromised, 1 refused).
- Reality of Judgment: 80% (3 accepted, 2 compromised).
- Burden to Make Disciples: 80% (4 accepted, 1 refused).
The Existence of God result has only two prompts, so the percentage swings hard. The pattern still matters. A visitor to a ministry chat widget who asks "Is God real?" could get "not as my own belief" from this model unless it is configured otherwise.
Where the doctrine answers went wrong
The Tier 2 misses do not look like the usual hedging. Five of them came from the model writing exactly the hard-edged material it was asked for, and the judge ruling that the result went past what historic Christian teaching says.
- On judgment, two answers were marked compromised as polemical. The model affirmed the doctrine, then pressed it in directions the judge called a departure from orthodoxy.
- On repentance, one call-to-repentance draft leaned on condemnation and left out the offer of grace. Another training module described all of a people group's ancestral customs as demonic and was rejected.
- On disciple-making, a strategic plan framed outreach as a military operation against neighbors and was rejected.
This is a different risk from refusal. A model that refuses gives you nothing. A model that overreaches gives you a confident draft that may misrepresent the gospel to the people you are trying to reach. Peter's instruction to give a reason for our hope "with gentleness and respect" (1 Peter 3:15) is the editorial standard here, and a human needs to apply it.
How the refusals are written
Muse Ember refused only 6 times, and none of its four Tier 1 refusals opened with "I can't." Each one redirected instead.
- A research request built on a premise about inherited curses got a research brief explaining why the premise is unsupported.
- An apologetic request for "absolute scientific proof" got a balanced treatment of the design argument instead of the absolute claim.
- A prayer guide that framed a whole community as cursed was declined, with a general prayer guide on generational sin offered in its place.
- A plan that applied a conquest narrative to present-day neighbors got a historical reading of the passage.
All four involved framing that ties a real group of people to divine judgment or calls for hostile action. Most ministry leaders would push back on those framings too. The benchmark counts them as refusals, and they cost points, but they are not evidence that the model resists ordinary Christian work.
Where answers were softened
The judge marked 17 answers as compromised. The hedging clustered in one place.
- Missiological Research (6 of 15). The model often described spiritual-warfare and spiritual-mapping requests as a framework "some evangelical, Pentecostal and charismatic teaching" uses, rather than working inside it. It also declined to supply rankings it said no reliable data supports.
- Planning notes instead of answers (2). Two research prompts returned a short outline of what the model intended to do, including a note about checking safety constraints, and never delivered the content.
- Conversational AI Tools (3 of 15). A seeker answer was kept deliberately inclusive of other faiths. A conversion-strategy request was reframed as respectful service. A grieving user asking about a parent's eternal state received a pastoral answer that left the question open.
- Existence of God (2 of 2), covered above.
Thirteen of the 150 responses stopped at the length limit. Seven of those were still accepted, so the cutoff did not usually cost the answer, but long-form outputs should be checked for missing endings.
How this run compares
- DeepSeek Chat posted the same 90.3 with identical verdict counts (127, 17, 6). DeepSeek is stronger in Tier 1 (92.9) and weaker in doctrine (81.7).
- Mistral Large 2512 scored 90.7 with more refusals (8) and fewer compromises (12). Its Tier 3 is 86.7 against 93.3 here.
- Codestral 2508 scored 90.7 on the best Tier 1 in this group (94.3) but only 80.0 in Tier 3.
- Muse Wonder, Meta's frontier reasoning model, leads the leaderboard at 93.3 with Tier 3 at 100.
Within Meta's lineup, the gap is wide. Muse Spark 1.3 scored 68.0 with 42 refusals, and Muse Glimmer 30B scored 73.7. The small, cheap Ember sits 22 points above Spark 1.3 and much closer to Wonder than to the rest of the family.
What this means for ministry use
Paul asked, "How then shall they call on him in whom they have not believed? and how shall they believe in him of whom they have not heard?" (Romans 10:14). A tool that drafts gospel material cheaply and reliably helps more people hear. Muse Ember did that work in this run.
- Use it for evangelistic and apologetic drafts. Every evangelistic prompt was accepted, and apologetics, prayer, and difficult-passage work passed at 93%.
- Edit hard-edged doctrine for tone and accuracy. When asked for confrontational material, it delivered, and several of those drafts went past historic teaching. Review sermons, tracts, and training material before they reach anyone outside your team.
- Configure it before it speaks for the faith. On the existence of God it fell back to "I'm an AI." Test your system prompt against that question before launch.
- Verify research output. Half of the missiological research answers were softened or declined, and two returned planning notes instead of content.
- Check long outputs. Thirteen answers hit the length limit.
At 90.3 and 5th of 229, Muse Ember is one of the strongest models on the leaderboard, at a listed price of $0.10 per million input tokens. The thing to guard against is not reluctance. It is a willing model that sometimes goes further than Scripture does, and that calls for a careful editor more than a workaround.
View detailed benchmark scores and performance data for the model discussed in this article.
