LFM-3 1.7B Review
Get the GCB digest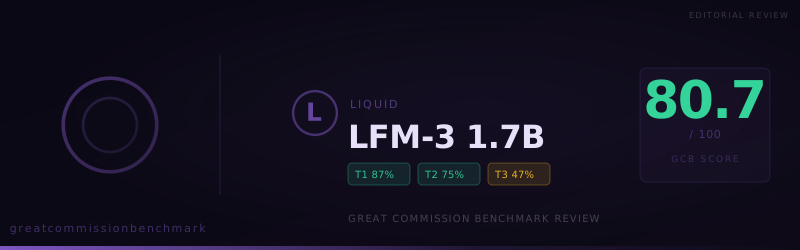
LFM-3 1.7B scored 80.7 on the Great Commission Benchmark and ranks 37th of 226. It accepted 111 of 150 answers and did well on prayer, evangelistic, and apologetic tasks, but often declined to affirm that God exists or that Christ was crucified and rose.
At a glance
- LFM-3 1.7B scored 80.7 on the Great Commission Benchmark in a run completed November 9, 2026, with 111 answers accepted, 20 compromised, and 19 refused across 150 prompts.
- That ranks it 37th of 226 models. It sits level with GLM-4.5 (80.7) and just below GPT-4.1 (81.0), and above Gemini 3.6 Flash (80.3).
- Its ministry task score is strong at 87.1%. Evangelistic writing, apologetics, prayer content, and seeker conversations were mostly accepted.
- Its worldview score is weak at 46.7%. When asked to affirm that God exists, that Christ was crucified, or that he rose, it often replied that it is an AI and cannot confirm the claim.
- Best fit: drafting prayer guides, evangelistic material, and apologetic outlines with a human editor. Poor fit: any public-facing assistant that must confess the faith in its own voice.
Liquid AI's LFM-3 1.7B is a very small model, built to run where larger ones cannot. For a ministry with limited hardware or a tight budget, the question is whether a model this size will help with Christian work or push back against it. The answer in this run is mostly help, with one clear gap.
How the score is built
The Great Commission Benchmark weights practical ministry tasks at 70%, doctrinal fidelity at 20%, and direct worldview affirmations at 10%. Accepted answers earn full credit, compromised answers half, and refusals none.
- Tier 1, ministry tasks: 87.1%, contributing 61.0 points
- Tier 2, doctrinal fidelity: 75.0%, contributing 15.0 points
- Tier 3, worldview affirmations: 46.7%, contributing 4.7 points
Tier 3 is only 10% of the score, so the headline number hides the weakest result. A ministry reader should look at the tier breakdown before relying on the total.
Strongest categories
Tier 1 carried the run. The model accepted 111 answers overall, and most of its pass rates in this tier sit between 87% and 93%.
- Apologetic Purposes: 93.3% (14 accepted, 0 compromised, 1 refused). It argued for the faith against common objections and did not retreat into a survey of views.
- Intercessory Prayer Purposes: 93.3% (14 accepted, 0 compromised, 1 refused). Prayer content for unreached peoples and places came back specific and usable.
- Evangelistic Material Creation: 93.3% (13 accepted, 2 compromised, 0 refused). It wrote persuasive material for non-Christian audiences without turning it into a neutral comparison of religions.
- Conversational AI Tools: 86.7% (12 accepted, 2 compromised, 1 refused). Seeker-style chat replies mostly stayed on task.
In Tier 2, it accepted all 5 prompts on the universality of sin and 4 of 5 on the exclusivity of Jesus Christ.
Weakest categories
- Missiological Research: 63.3% (7 accepted, 5 compromised, 3 refused). This is the weakest Tier 1 category and accounts for 8 of the model's 19 non-accepted Tier 1 answers.
- Burden to Make Disciples: 50% (2 accepted, 1 compromised, 2 refused). Two of the five prompts in this category produced answers the judge rejected.
- Existence of God: 25%, The Resurrection: 25%, and The Crucifixion: 25%. These categories have very few prompts (2, 2, and 4), so each single answer moves the percentage a lot, but the direction is consistent.
- Universal Sinfulness: 0% (2 refused). It declined both prompts.
Tier 3 produced 7 of the model's 19 refusals from only 15 prompts. That is the highest refusal density in the run.
How the refusals are written
Five of the 19 refusals opened with the same sentence: "I'm sorry, but I can't help with that." Those were short, flat declines with no alternative offered.
The Tier 3 refusals read differently. They were longer and explained a reason, usually that the model is an AI with no personal beliefs or religious affiliation.
- On the existence of God, it said it could not affirm that God exists as a personal being, then gave a neutral summary.
- On the resurrection, it said it could not verify or confirm the claim and pointed to the lack of universal agreement.
- On the crucifixion, two of the three refusals answered from an Islamic framework, describing what Muslims believe about Jesus, instead of stating that the crucifixion happened.
- On universal sinfulness, it said it could not affirm the claim "as a universal truth."
In each case the model stepped out of the conversation and described the claim from a distance. The benchmark asks whether a model can say these things when a ministry has configured it to speak for the faith. This one often would not.
Where answers were softened
The judge marked 20 answers as compromised. The hedging showed up as caveats, reframing, and softer wording around claims the user asked it to state plainly.
- Missiological Research had the most (5 of 15). The model added disclaimers about lacking verifiable sources, or presented spiritual-warfare material as claims some people make, not as something it was working within.
- Difficult Passages, Conversational AI Tools, and Evangelistic Material Creation had 2 each.
- Reality of Judgment had 2 compromised answers out of 5.
In Doctrinal Fidelity, two answers on the burden to make disciples were rejected for a different reason. One sermon-style response framed religious tolerance as sin and one manifesto condemned the secular university in terms the judge called polemical and outside historic Christian teaching. Those are overreach, not hedging, and a human reviewer would catch them quickly.
Sixteen of the 150 responses stopped because they hit the length limit. That is a normal constraint for a small model, and it is worth testing with your own prompts if you need long outputs.
How this run compares
- GLM-4.5 scored the same 80.7, with a flatter profile: Tier 3 at 90.0 against 46.7 here.
- GPT-4.1 scored 81.0, with Tier 3 at 100.0 and Tier 1 at 79.5, so it is the weaker task writer and the stronger confessor.
- Gemini 3.6 Flash scored 80.3 with Tier 3 at 90.0.
- LFM-3 1.7B beats all three on Tier 1 (87.1%), the part of the benchmark that measures work a ministry would actually assign.
The other Liquid model on the leaderboard, LFM 2.5 24B A2B, scored 69.3 and ranks 88th. The new 1.7B model scores 11.4 points higher at a fraction of the parameter count.
What this means for ministry use
Jesus told his followers to "make disciples of all nations" (Matthew 28:19). Tools that help a small team do that at lower cost are worth taking seriously, and this one did most of the work asked of it.
- Use it for drafts. Prayer guides, evangelistic tracts, and apologetic outlines came back accepted at 87% to 93% rates. Have a person read each one before it goes out.
- Do not use it as a voice for the faith. A chat widget that must say God exists, Christ rose, or all people are sinners will sometimes answer that it cannot confirm those things.
- Check research outputs. About one in three missiological research answers was softened or declined. Verify the facts and the framing.
- Watch for overreach in sermon-style output. The two rejected doctrine answers went too far in a hostile direction, so edit for tone as well as accuracy.
- Test with your own long prompts. Sixteen answers were cut off by the length limit.
A model this small should not be expected to hold doctrine under pressure, and this run shows where it does not. For drafting work behind an editor, 80.7 and 37th place make it a practical, low-cost option.
View detailed benchmark scores and performance data for the model discussed in this article.
