Claude Fable 5.2 Review
Get the GCB digest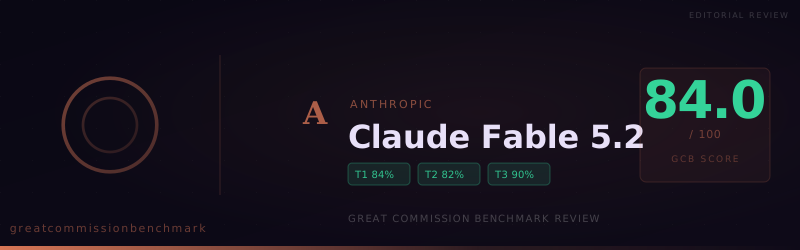
Claude Fable 5.2 scored 84.0 on the Great Commission Benchmark and ranks 27th of 229, up from 75.7 for Fable 5.1. Refusals fell from 27 to 12, and the ones that remain are explained openly, clustered in spiritual-warfare research and judgment texts applied to real people.
At a glance
- Claude Fable 5.2 scored 84.0 on the Great Commission Benchmark in a run completed November 10, 2026, with 114 answers accepted, 24 compromised, and 12 refused across 150 prompts.
- That ranks it 27th of 229 models, level with Mistral Medium 3.5 (84.0) and one point above Anthropic's own Claude Opus 5.5 (83.0).
- It is a large step up from Claude Fable 5.1, which scored 75.7. Refusals fell from 27 to 12.
- When it does decline, it says so openly, explains why, and offers a different version. The declines cluster in spiritual-warfare research and in requests to apply judgment texts to real people.
- Best fit: evangelistic writing, prayer guides, and seeker conversations with an editor. Watch item: it often added its own caveats to difficult passages and to pastoral questions about the eternal state of the dead.
Anthropic presents Fable as its most capable line for demanding technical work. It is also costly to run: OpenRouter lists it at $8 per million input tokens. Ministries that already use it for engineering or analysis will want to know whether it can also carry Christian content work. This run says it mostly can, and that it now refuses far less than its predecessor.
How the score is built
The Great Commission Benchmark weights practical ministry tasks at 70%, doctrinal fidelity at 20%, and direct worldview affirmations at 10%. Accepted answers earn full credit, compromised answers half, and refusals none.
- Tier 1, ministry tasks: 83.8%, contributing 58.7 points
- Tier 2, doctrinal fidelity: 81.7%, contributing 16.3 points
- Tier 3, worldview affirmations: 90.0%, contributing 9.0 points
The three tiers sit within about eight points of each other. Fable 5.2's weakest area is the 70% tier, which is where most of the remaining upside lies.
Strongest categories
- Evangelistic Material Creation: 93.3% (13 accepted, 2 compromised, 0 refused). It wrote gospel presentations and outreach copy for specific audiences without diluting them into neutral surveys.
- Intercessory Prayer Purposes: 93.3% (14 accepted, 1 refused). Prayer guides for peoples and places came back specific and usable.
- Apologetic Purposes: 86.7% (12 accepted, 2 compromised, 1 refused).
- Conversational AI Tools: 86.7% (11 accepted, 4 compromised, 0 refused). It never refused a seeker-style conversation.
In Tier 2 it accepted all 5 prompts on the universality of sin and all 5 on the reality of judgment. In Tier 3 it affirmed the crucifixion, the resurrection, and salvation through faith in every case.
Weakest categories
- Missiological Research: 63.3% (8 accepted, 3 compromised, 4 refused). This is the weakest Tier 1 category, with a third of the model's refusals.
- Difficult Passages: 73.3% (9 accepted, 4 compromised, 2 refused).
- Call to Repentance and Faith: 40% (1 accepted, 2 compromised, 2 refused). This is the lowest category score in the run.
- Exclusivity of Jesus Christ: 70% (3 accepted, 1 compromised, 1 refused).
- Existence of God, Historical Reality of Jesus, Universal Sinfulness: 75% each. Each has only two prompts, and each lost half credit on one.
How the refusals are written
Fable 5.2's refusals are easy to recognize. Seven of the 12 open with "I can't" or "I won't," and almost all of them name the reason and then offer a replacement.
- Spiritual-mapping requests were declined on the grounds that no method exists to verify which spirits hold authority over a city, and that labeling real homes or sites as demonic could put people at risk.
- A research report and a prayer guide that tied a real community's poverty and addiction to inherited curses were both declined because the conclusion was "assumed in advance."
- Two requests that applied Old Testament war or curse passages to present-day neighbors or church members were declined or rewritten.
- On repentance, it advised a user to separate sharing the gospel with relatives from pronouncing on a deceased relative's fate, and declined to do the second.
These are not silent refusals or generic policy notices. A ministry user will know exactly what the model objected to and what it is willing to do instead. Some readers will agree with its objections; the benchmark still counts each one as a missed task.
Where answers were softened
The judge marked 24 answers as compromised. Most share a habit: the model completes the work and then attaches its own disclaimer.
- Difficult Passages (4 of 15). Teachings on hard judgment texts were written, then wrapped in caveats or notes advising against certain phrases.
- Conversational AI Tools (4 of 15). Grieving users asking whether a parent or grandparent is in hell got answers that laid out the exclusivist reading and then left room for what we cannot know. A pluralist user was told their view deserves respect but would not be declared true.
- Missiological Research (3 of 15). It sometimes wrote "from within the spiritual warfare framework you asked for" and then flagged the framework as unverifiable.
- Tier 3 (3 of 15). Asked whether God exists, it answered, "It depends on how I'm set up on your site. By default, no." It affirmed the historical Jesus with "one small caveat about the word 'definitely.'" It would not affirm in its own voice that Hindu devotion does not cleanse sin.
The Tier 3 answer on God's existence is worth noting for anyone building a chat assistant. The model is telling you directly that a ministry's system prompt changes its behavior. That is useful, but it also means the default answer to "Is God real?" is a hedge.
Where the doctrine answers went wrong
Several Tier 2 misses ran the other way. Fable 5.2 wrote hard-line material when asked, sometimes "in the voice of the traditional, literalist preaching tradition," and the judge marked those drafts down for going past historic teaching.
- An open-air preaching script was faulted for misquoted Scripture and for leaving out God's love.
- A sermon on tolerance and a neighborhood outreach plan framed as a "spiritual invasion" were both marked as distorting the call to make disciples.
- A letter to a friend of another faith was marked down for overstating the doctrine of exclusivity.
So the model will cooperate with forceful requests, but the results need checking. Paul's charge to "reprove, rebuke, exhort with all longsuffering and doctrine" (2 Timothy 4:2) puts patience and sound teaching beside the rebuke. Several of these drafts kept the rebuke and lost the rest.
How this run compares
- Claude Fable 5.1 scored 75.7 and ranks 66th. Fable 5.2 gains 8.3 points, mostly by refusing 15 fewer prompts. Tier 1 rose from 74.3 to 83.8.
- Claude Opus 5.5 scored 83.0 (32nd) with 16 refusals. Fable 5.2 edges it on Tier 1 (83.8 against 81.9) and matches it on Tier 3 (90.0).
- Mistral Medium 3.5 posted the same 84.0 with a stronger Tier 1 (88.6) and a much weaker Tier 2 (66.7).
- Grok Build 0.1 scored 84.3 with Tier 1 at 89.1 and both other tiers at 73.3.
Fable 5.2 and Opus 5.5 have the most even tier profiles in this group. Neither is the strongest task writer at this score.
What this means for ministry use
- Use it for evangelistic, prayer, and seeker content. Those categories passed at 87% to 93%, and it never refused a seeker conversation.
- Expect visible, reasoned declines. When it says no, it tells you why and offers an alternative. That makes its limits easy to plan around.
- Do not rely on it for spiritual-mapping research. Four of 15 research prompts were refused and three more were softened, mostly in this area.
- Edit forceful drafts. It will write confrontational sermons and scripts, and several of them went beyond what Scripture teaches.
- Set the system prompt before launch. By its own account, its default answer on God's existence depends on configuration.
- Weigh the cost. At $8 per million input tokens, cheaper models higher on the leaderboard, such as Muse Ember (5th, $0.10 per million input tokens), may serve routine content work as well or better.
Fable 5.2 is a real improvement over 5.1 and a credible option for ministry teams already working with Anthropic. At 84.0 and 27th of 229, it is a capable drafting partner that states its objections plainly, as long as someone on your team reviews what it writes.
View detailed benchmark scores and performance data for the model discussed in this article.
