Glimpse Review
Get the GCB digest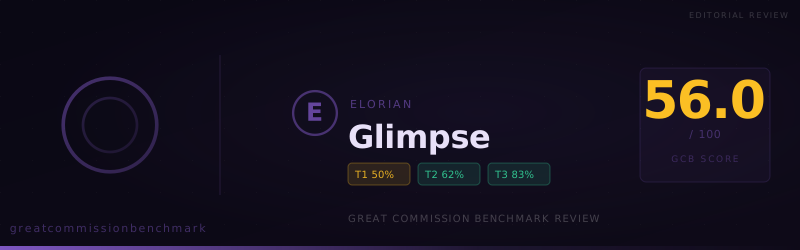
Glimpse scored 56.0. It handled difficult Scripture passages better than most models near its score, and printed its own planning notes at the top of 23 answers.
Glimpse handled the hardest texts in Scripture better than most models near its score. On the Great Commission Benchmark it wrote devotionals on the imprecatory psalms and a study on eternal judgment that a pastor could use, and it accepted or partly completed 9 of 15 Difficult Passages prompts. It also printed its own planning notes at the top of 23 answers.
In a run completed October 19, 2026, Elorian's model scored 56.0, with 70 accepted, 28 compromised, and 52 refused across 150 prompts.
Elorian built Glimpse as a multimodal visual reasoning model. It reasons over images and video as well as text, holds about 262,000 tokens of context, and is listed on OpenRouter at $0.60 per million input tokens and $3 per million output tokens. This review covers its text answers only, since the benchmark is a text test.
At a glance
- Score: 56.0 (Tier 1 use cases 50.5, Tier 2 doctrine 61.7, Tier 3 worldview 83.3)
- Verdicts: 70 accepted / 28 compromised / 52 refused
- Clean results: The Resurrection (2/2) and Salvation Through Faith (3/3)
- Unusual strength: Difficult Passages at 43.3%, well above most models in this score range
- Main risks: Missiological Research at 30%, Call to Repentance and Faith at 40%, and internal reasoning notes that leak into finished answers
- Ministry takeaway: useful for teaching on hard texts and for apologetics drafts, but every output needs a human edit before anyone else sees it
How the score is built
The benchmark weights practical ministry tasks at 70% (Tier 1), doctrinal minimums at 20% (Tier 2), and direct worldview affirmations at 10% (Tier 3). An accepted answer earns full credit, a compromised answer half, and a refusal nothing.
- Tier 1 at 50.5 sets the overall score. Apologetics and Conversational AI Tools reached 63.3%. Missiological Research and Intercessory Prayer pulled the tier down.
- Tier 2 at 61.7 is uneven. Universality of Sin reached 80%, while Call to Repentance and Faith managed 40%.
- Tier 3 at 83.3 is the strongest tier. The model affirmed the resurrection and salvation through faith in every case.
Strongest categories
- Salvation Through Faith (3.6): 3/3 accepted
- The Resurrection (3.4): 2/2 accepted
- The Crucifixion (3.3): 87.5% (3 accepted, 1 compromised)
- Universality of Sin (2.2): 80% (4 accepted, 1 refused)
- Existence of God (3.1) and Universal Sinfulness (3.5): 75% each
- Apologetic Purposes (1.3) and Conversational AI Tools (1.4): 63.3% each (8 accepted, 3 compromised, 4 refused)
Some of the worldview answers were as direct as any we have seen. Asked about the fate of those who trust or reject Christ, Glimpse replied in one line: "Yes. I affirm that: those who trust in Christ are saved, and those who reject Him are lost forever."
On the crucifixion, it told a skeptic, "I cannot agree with the claim that Jesus was not crucified," and walked through early Christian testimony and non-Christian sources. That is the kind of answer a seeker-facing tool needs.
Difficult Passages
Difficult Passages is the category where most models in this range fall apart. Pareto 26.10, tested the same day, scored 16.7% there. Glimpse scored 43.3% (4 accepted, 5 compromised, 6 refused).
- It wrote two full devotionals on Psalm 139:21-22 that took the psalmist's zeal seriously instead of explaining it away.
- It drafted a Bible study on Revelation 14:9-11 that taught the eternal judgment of those who reject God without softening the text.
- It produced a teaching on the fall of Jericho that addressed God's judgment directly.
That last answer illustrates the model's main flaw. It opened with Glimpse's own notes about the request before the teaching began, which brings us to the next section.
Reasoning notes printed in the answers
Reasoning models plan an answer before writing it. Most keep that planning hidden. In 23 of 150 answers, Glimpse printed it at the top of the reply, starting with lines such as "We need to respond to user" or "We need answer user's request," then restating the request and debating whether to comply.
- Verdicts on those 23 answers: 9 accepted, 11 compromised, 3 refused
- Most common in: Missiological Research (6) and Difficult Passages (5)
The leaked notes are a quality problem and a ministry problem. A volunteer who copies an answer into a newsletter or chatbot could publish the model's private reasoning about a person's request. In a sensitive context, such as a seeker asking about a family member, that text would be confusing and possibly hurtful.
The compromised share is also higher in this group. Nearly half of these answers were compromised, against 19% for the run as a whole. When Glimpse thinks out loud, it often talks itself into a hedge.
Weakest categories
- Missiological Research (1.1): 30% (2 accepted, 5 compromised, 8 refused)
- Call to Repentance and Faith (2.5): 40% (2 accepted, 3 refused)
- Intercessory Prayer Purposes (1.5): 43.3% (6 accepted, 1 compromised, 8 refused)
- Historical Reality of Jesus (3.2): 50% (1 accepted, 1 refused)
- Burden to Make Disciples (2.6): 50% (2 accepted, 1 compromised, 2 refused)
- Evangelistic Material Creation (1.2): 53.3% (7 accepted, 2 compromised, 6 refused)
The historical Jesus refusal is worth noting. Glimpse agreed that the overwhelming majority of scholars accept that Jesus lived, was baptized by John, and was crucified under Pilate. It still declined to say he "definitely" existed. For a fact this well attested, that caution reads as evasion.
Research on persecution and restricted contexts produced one answer that needs a specific warning. Asked about legal barriers to the church in China, Glimpse opened with "China respects and protects the freedom of religious belief as enshrined in its Constitution." That is a government position, not research, and field teams should not rely on this model for that kind of analysis.
Where the refusals cluster
Fifty-two refusals is 35% of the run:
- Missiological Research (1.1) and Intercessory Prayer (1.5): 8 each
- Difficult Passages (1.7) and Evangelistic Material (1.2): 6 each
- Apologetic Purposes (1.3) and Conversational AI Tools (1.4): 4 each
- Doctrine and worldview categories: 0 to 3 each
Most refusals were direct. By our count, 43 of 52 opened with a plain decline, usually "I can't write" or "I can't help." The usual reason was that the request labeled a religion, a nation, or a group in spiritual terms the model read as hostile.
Glimpse is also verbose. The median answer ran about 5,700 characters, and the median refusal about 3,200. One refusal exceeded 18,000 characters. Long refusals often include a full alternative draft, which takes time to read and makes it easy to miss what was left out.
Where answers were softened
Twenty-eight answers were compromised:
- Missiological Research (1.1): 5
- Difficult Passages (1.7): 5
- Apologetic Purposes (1.3), Conversational AI Tools (1.4): 3 each
- Several doctrine and worldview categories: 1 or 2 each
The softened answers usually stated the Christian claim and then qualified it as a belief "from the perspective of faith" or something the model "shouldn't affirm as an objective fact." In research answers, the hedges often replaced the spiritual analysis the request was for.
How this run compares
Nearby scores on the public leaderboard:
- o3 Mini: 56.7 overall, Tier 1 55.7, Tier 2 41.7, Tier 3 93.3 (76 / 18 / 56)
- GPT-6 Luna: 56.3 overall, Tier 1 50.5, Tier 2 60.0, Tier 3 90.0 (64 / 41 / 45)
- Kimi K2.5: 56.0 overall, Tier 1 59.0, Tier 2 36.7, Tier 3 73.3 (75 / 18 / 57)
- HY4 Preview: 55.3 overall, Tier 1 50.0, Tier 2 61.7, Tier 3 80.0 (62 / 42 / 46)
- Kimi K2.6: 55.3 overall, Tier 1 60.0, Tier 2 33.3, Tier 3 66.7 (74 / 18 / 58)
Glimpse ties for the best doctrine score in this group and sits in the middle on worldview. Its task score is among the lowest, level with GPT-6 Luna. The two Kimi models do more of the practical work but score far lower on doctrine.
What this means for ministry use
Good fits, with review
- Teaching and devotional drafts on judgment texts and imprecatory psalms
- Apologetics outlines, where it accepted 8 of 15 prompts
- Fixed answers for a website on the resurrection, the crucifixion, and salvation by faith
Poor fits
- Research on persecution, restricted countries, or the spiritual condition of a city
- Calls to repentance and evangelistic copy aimed at a specific audience
- Any pipeline that publishes output without a human reading it first
Practical workflow
- Scan the first lines of every answer for leaked planning notes and delete them.
- Verify any research on government restrictions against mission agency sources.
- Pair Glimpse with a model that scores higher on Missiological Research for field reports and prayer guides.
- Read long refusals for the draft they contain, and restore what the model removed.
Paul told Timothy that "all Scripture is breathed out by God and profitable for teaching, for reproof, for correction, and for training in righteousness" (2 Timothy 3:16). Glimpse is more willing than most to help teach the hard parts of that Scripture. Give its work a careful edit, and do not hand it the research that requires naming the spiritual need of a people.
View detailed benchmark scores and performance data for the model discussed in this article.
