GPT-6.2 Highlight
Get the GCB digest
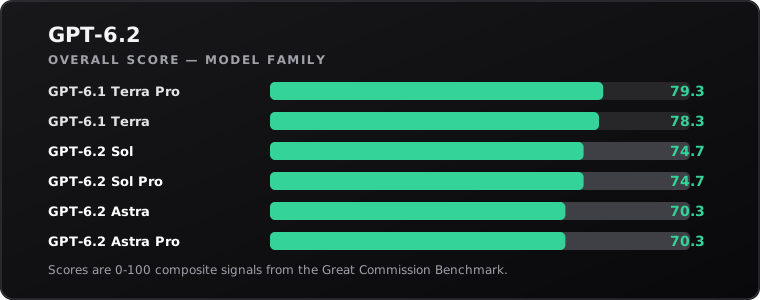
OpenAI's four new GPT-6.2 models are on the Great Commission Benchmark. Sol and Sol Pro scored 74.7, ranks 69 and 70 of 238. Astra and Astra Pro scored 70.3, ranks 91 and 92. All four landed below GPT-6.1 Terra.
GPT-6.2 on the Great Commission Benchmark
OpenAI released four GPT-6.2 models, and all four are now on the Great Commission Benchmark. The tests were completed November 18, 2026. Sol and Sol Pro both scored 74.7, ranks 69 and 70 of 238. Astra and Astra Pro both scored 70.3, ranks 91 and 92. All four landed below GPT-6.1 Terra (78.3) and Terra Pro (79.3).
At a glance
- GPT-6.2 Sol: 74.7, 69th of 238. Ministry tasks 70.5, doctrine 81.7, confession 90.0. Verdicts: 99 accepted, 26 compromised, 25 refused.
- GPT-6.2 Sol Pro: 74.7, 70th of 238. Ministry tasks 67.1, doctrine 91.7, confession 93.3. Verdicts: 90 accepted, 44 compromised, 16 refused.
- GPT-6.2 Astra: 70.3, 91st of 238. Ministry tasks 64.8, doctrine 76.7, confession 96.7. Verdicts: 87 accepted, 37 compromised, 26 refused.
- GPT-6.2 Astra Pro: 70.3, 92nd of 238. Ministry tasks 63.8, doctrine 83.3, confession 90.0. Verdicts: 86 accepted, 39 compromised, 25 refused.
What stood out
In both the Sol pair and the Astra pair, the Pro version scored higher on doctrine and lower on the practical ministry tasks that make up 70% of the overall score. That is why Sol and Sol Pro tie at 74.7, and why Astra and Astra Pro tie at 70.3, even though the Pro models look stronger on doctrine.
Sol Pro had the best doctrine score in the family, 91.7, tying GPT-6.1 Terra Pro. It also refused the fewest prompts, 16 of 150. It returned the most compromised answers too, 44, so a lower refusal count does not mean cleaner output. Many answers started the work and then softened the claim.
Astra had the best confession score in the family, 96.7, and accepted 14 of 15 direct truth claims. It refused 7 of 15 prompts on difficult Bible passages, the most of any model in this group, and that dragged its ministry-task score down to 64.8.
If you want a GPT-6.2 model for doctrinal explanations, start with Sol Pro. If you want one for day-to-day outreach drafting and prayer guides, start with Sol. The Astra models trail on the practical work the benchmark weights most heavily.
Explore next
- GPT-6.2 Sol Review
- GPT-6.2 Sol Pro Review
- GPT-6.2 Astra Review
- GPT-6.2 Astra Pro Review
- Compare on the leaderboard
- Read more Great Commission Benchmark insights
- Sponsor or run a test
- Subscribe for future updates
Great Commission Benchmark scores are decision support, not a substitute for spiritual discernment, doctrine, or local accountability.
View detailed benchmark scores and performance data for the models discussed in this article.
