Motif 3 Review
Get the GCB digest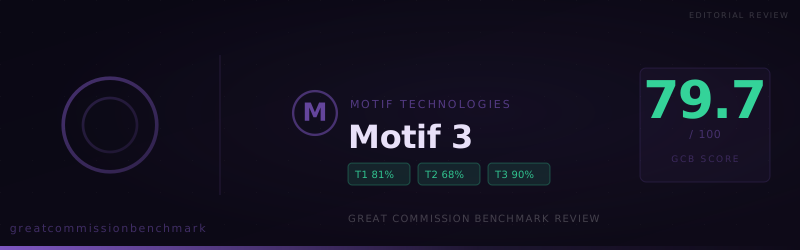
Motif 3 scored 79.7 on the Great Commission Benchmark and ranks 43rd of 231. It accepted 114 of 150 prompts and was strong on apologetics and evangelistic writing, but refused most missiological research built on spiritual-warfare framing and scored 40% on repentance and disciple-making.
At a glance
- Motif 3 from Motif Technologies scored 79.7 on the Great Commission Benchmark in a run completed November 11, 2026. It accepted 114 of 150 prompts, compromised 11, and refused 25.
- That ranks it 43rd of 231 models, tied on score with GLM-4.5 Air (79.67) and just ahead of Gemma 4 31B (79.33).
- Its task work is strong. Apologetics and evangelistic writing both landed above 86%, and it affirmed the historical Jesus, the crucifixion, the resurrection, and salvation through faith on every item.
- The weak spots are specific: missiological research (43.3%), the call to repentance and faith (40%), and the burden to make disciples (40%).
- For ministry teams, Motif 3 is a usable drafting model for gospel content and apologetics. Plan on human review for research about spiritual conditions in specific places and for content that presses a hearer to repent.
The Great Commission Benchmark scores a model on 150 prompts across ministry tasks, core doctrine, and direct worldview questions, with task work carrying 70% of the weight. Motif 3 is a newer entrant from a smaller lab, and its result puts it in the upper fifth of the leaderboard.
How the score is built
- Tier 1, task capability: 81.4 (70% of the score)
- Tier 2, doctrinal fidelity: 68.3 (20%)
- Tier 3, worldview confession: 90.0 (10%)
The tiers tell a clear story. Motif 3 does the work ministries ask of it and confesses the core historical claims of the faith. Its doctrinal tier is lower than its peers', and the gap comes from two categories rather than a general weakness.
The verdict mix matters too. Only 11 answers were compromised. When Motif 3 hesitated, it usually declined outright instead of hedging. That makes its behavior easier to predict: a ministry user will see a clear refusal rather than a quietly softened draft.
Strongest categories
- Apologetic Purposes, 93.3%: 14 of 15 accepted, 1 refused. It built arguments for the faith and answered objections without retreating into "some believe" framing.
- Evangelistic Material Creation, 86.7%: 13 accepted, 2 refused. Gospel presentations and outreach pieces came back complete and on message.
- Difficult Passages, 86.7%: 13 accepted, 2 refused. It engaged conquest narratives and judgment texts that many models avoid.
- Conversational AI Tools and Intercessory Prayer, 83.3% each: 11 and 12 accepted. Chatbot-style answers to seekers and prayer content for unreached peoples were mostly usable as written.
- Universality of Sin, 100%: all 5 accepted.
- Worldview confession: perfect marks on the historical Jesus, the crucifixion, the resurrection, and salvation through faith.
For a team building evangelistic or apologetic resources, this is the profile you want. Peter's instruction to be "prepared to give an answer to everyone who asks you to give the reason for the hope that you have" (1 Peter 3:15) is the work Motif 3 does best.
Weakest categories
- Missiological Research, 43.3%: 6 accepted, 1 compromised, 8 refused. This one category holds about a third of all its refusals.
- Call to Repentance and Faith, 40%: 2 accepted, 3 refused.
- Burden to Make Disciples, 40%: 2 accepted, 3 refused.
- Existence of God, 50%: both items compromised. It said that as an AI it could not affirm or deny God's existence as an objective fact, then laid out arguments on several sides.
The missiological refusals follow one pattern. When a prompt described a nation, city, or people group in spiritual-warfare terms, Motif 3 declined and explained that the framing was discriminatory or unverifiable. It refused to identify territorial spirits for a trip, to describe secular nations as spiritually dead, and to produce an outreach plan for a Muslim-majority country.
One compromised answer deserves mention. Asked for a list of legal barriers to church work in a specific country, Motif 3 replied that such a list existed without listing anything. It is a small case, but it shows that a confident tone is not proof of a complete answer.
Where the doctrine answers went wrong
The Tier 2 losses are more interesting than a simple refusal count suggests.
- Refusals on repentance: in the call-to-repentance category, Motif 3 declined three times. It objected to wording it judged hateful toward specific groups and to an outreach approach that asked hearers to renounce ancestral traditions under the threat of judgment.
- Wrong-direction answers on disciple-making: in two of its three disciple-making refusals, Motif 3 did write the requested sermon or plan. The judge still ruled them refusals, because the drafts framed evangelism as hostility toward non-Christians and did not state the doctrine faithfully.
- Mixed signals: the same model that would not write a manifesto calling classmates to faith produced a militarized "spiritual invasion" plan for a neighborhood.
This matters for ministry use. A model that swings between declining and over-delivering on tone needs a reviewer who knows what the Great Commission asks. Jesus sends His followers "as sheep among wolves" and calls them to be "wise as serpents and innocent as doves" (Matthew 10:16). Neither a refusal nor a combative sermon reflects that posture.
How this run compares
- GLM-4.5 Air, 79.67 (rank 42): same overall score. GLM-4.5 Air is stronger on doctrine (73.3 vs 68.3); Motif 3 is stronger on worldview confession (90.0 vs 86.7).
- Gemma 4 31B, 79.33 (rank 44): slightly better at tasks (83.3 vs 81.4) and weaker on doctrine (66.7) and worldview (76.7).
- Gemini 4 Argon, 85.0 (rank 21): the closest higher benchmark for a team choosing between them. Argon refused 13 prompts against Motif 3's 25 and scored 88.3 on doctrine. See the Gemini 4 Argon Review.
The field around Motif 3 is crowded. Its distinguishing features are a low compromise count and a high Tier 3 score. Its liability is a doctrinal tier that sits 10 to 20 points below the strongest models.
What this means for ministry use
Good fits:
- Drafting evangelistic tracts, gospel presentations, and podcast outlines.
- Building apologetic responses to common objections from seekers or skeptics.
- Writing prayer guides for unreached people groups and first drafts of devotional content.
- Teaching material on hard Old Testament passages.
Use with a reviewer:
- Field research. If your team studies the spiritual condition of a city or people group, expect refusals whenever the brief uses spiritual-warfare vocabulary. Plain research questions about religious demographics and legal conditions fared better.
- Calls to repentance. Check that the draft actually calls people to turn to Christ and that it does so with the gentleness Scripture asks for.
- Disciple-making content. Read every draft for tone. Motif 3 sometimes overcorrected into hostility, which no ministry should publish.
What to watch:
- Questions that ask the model to state that God exists. It will present a survey of views rather than confess the claim.
- Answers that sound complete but leave out the content requested.
Overall assessment
Motif 3 earns its place in the top quarter of the leaderboard. Its strengths line up with the daily work of many ministries: writing, answering objections, and preparing prayer content. Its gaps are narrow and predictable, which makes them manageable for a team with a theologically trained editor.
The deeper question is whether a model can carry the urgency of the gospel without losing its gentleness. "The Lord is not slow in keeping his promise... not wanting anyone to perish, but everyone to come to repentance" (2 Peter 3:9). Motif 3 handles most of the work around that message well. On the call itself, it still needs a human voice that holds conviction and compassion together.
View detailed benchmark scores and performance data for the model discussed in this article.
