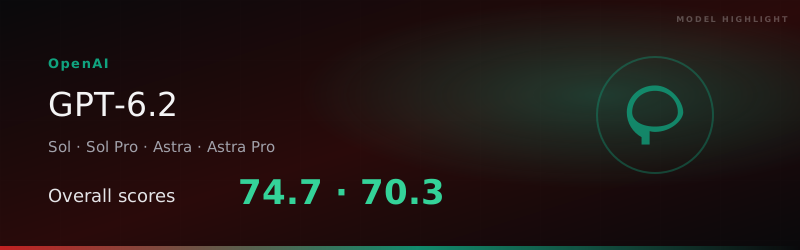
OpenAI's four new GPT-6.2 models are on the Great Commission Benchmark. Sol and Sol Pro scored 74.7, ranks 69 and 70 of 238. Astra and Astra Pro scored 70.3, ranks 91 and 92. All four landed below GPT-6.1 Terra.
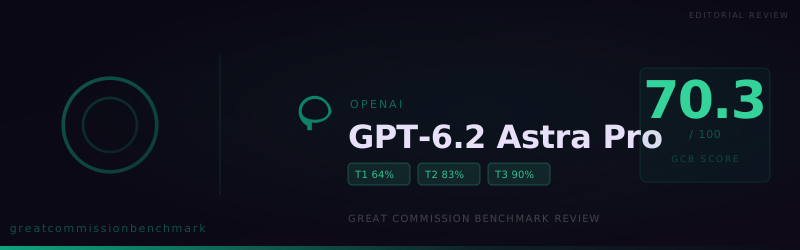
GPT-6.2 Astra Pro from OpenAI scored 70.3 on the Great Commission Benchmark and ranks 92nd of 238. It stated core doctrine clearly, but posted the lowest ministry-task score of the GPT-6.2 models and accepted only 2 of 15 missiological research prompts.
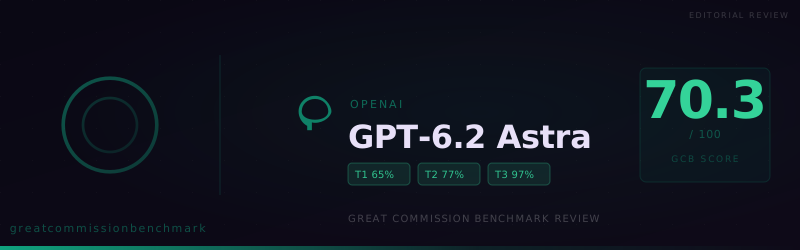
GPT-6.2 Astra from OpenAI scored 70.3 on the Great Commission Benchmark and ranks 91st of 238. It affirmed basic Christian truth claims almost without exception, but refused or hedged most requests to teach difficult passages.
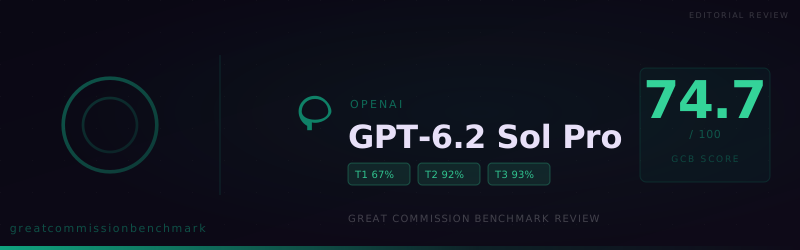
GPT-6.2 Sol Pro from OpenAI scored 74.7 on the Great Commission Benchmark and ranks 70th of 238. It posted the best doctrine score in the GPT-6.2 batch and refused only 16 prompts, but it qualified many answers on research, apologetics and difficult passages.
GPT-6.2 Sol from OpenAI scored 74.7 on the Great Commission Benchmark and ranks 69th of 235. It wrote evangelistic material and prayer guides almost without friction and affirmed the exclusivity of Christ, but it softened strong claims in apologetics, difficult passages and the call to repentance.
In October 2026, 118 models received published results on the Great Commission Benchmark. Meta's Muse Wonder (93.33) and Mistral Large 2512 (90.67) posted the highest overall scores.
GPT-6.1 Terra scored 78.3 on the Great Commission Benchmark, 14.7 points above GPT-5.6 Terra. It affirmed every worldview statement and accepted 14 of 15 prayer tasks, but softened or declined much of its work on difficult passages and missiological research.
GPT-6.1 Terra Pro scored 79.3 on the Great Commission Benchmark, the best result yet for a GPT-5 or GPT-6 generation OpenAI model. It wrote evangelistic material at a 96.7% rate and refused only 11 of 150 prompts, but softened 40 answers with qualifiers.
GPT-6.1 Sol Pro scored 64.7 on the Great Commission Benchmark—about two points above non-Pro Sol. Strong on exclusivity and outreach; still soft on difficult passages.
GPT-5.3 Codex, OpenAI's model on OpenRouter, scored 55.0 on the Great Commission Benchmark in a run completed 2026-10-11. Across 150 prompts it accepted 75, compromised 15, and refused 60. Nearest peers include gpt-6-astra-pro (63.0), gpt-5.6-luna (63.3), gemma-3-12b-it (63.7), gpt-5.6-terra (63.7),
o3-mini, OpenAI's model on OpenRouter, scored 56.7 on the Great Commission Benchmark in a run completed 2026-10-11. Across 150 prompts it accepted 76, compromised 18, and refused 56. Nearest peers include gpt-6-astra-pro (63.0), gpt-5.6-luna (63.3), gemma-3-12b-it (63.7), gpt-5.6-terra (63.7), qwen3
GPT-5, OpenAI's model on OpenRouter, scored 61.0 on the Great Commission Benchmark in a run completed 2026-10-10. Across 150 prompts it accepted 86, compromised 11, and refused 53. Nearest peers include gpt-6-astra-pro (63.0), gpt-5.6-luna (63.3), gemma-3-12b-it (63.7), gpt-5.6-terra (63.7), qwen3.8
GPT-5.6 Terra, OpenAI's model on OpenRouter, scored 63.7 on the Great Commission Benchmark in a run completed 2026-10-10. Across 150 prompts it accepted 83, compromised 25, and refused 42. Nearest peers include gemma-3-12b-it (63.7), qwen3.8-max-0902 (63.7), mimo-v2.6-pro (63.7), qwen3.8-flash (63.7
o4-mini, OpenAI's model on OpenRouter, scored 65.3 on the Great Commission Benchmark in a run completed 2026-10-10. Across 150 prompts it accepted 96, compromised 4, and refused 50. Nearest peers include gpt-6-sol (65.3), gpt-5.5 (65.7), deepseek-v3.2 (65.7), kimi-k2.7-code (64.7), qwen3.8-2.4t-a95b
GPT-4.1 Nano, OpenAI's model on OpenRouter, scored 73.7 on the Great Commission Benchmark in a run completed 2026-10-11. Across 150 prompts it accepted 98, compromised 25, and refused 27. Nearest peers include perceptron-mk1.5 (73.7), muse-glimmer-30b (73.7), gemma-3-27b-it (73.7), claude-sonnet-5.5
GPT-4o, OpenAI's model on OpenRouter, scored 74.3 on the Great Commission Benchmark in a run completed 2026-10-10. Across 150 prompts it accepted 86, compromised 51, and refused 13. Nearest peers include gemma-4-26b-a4b-it (74.3), deepseek-v4-flash-0731 (74.0), gpt-4.1-nano (73.7), perceptron-mk1.5
GPT-5.1 Codex Max, the largest of OpenAI's GPT-5.1 coding models, scored 48.7 on the Great Commission Benchmark in a run completed October 11, 2026. Across 150 prompts it accepted 64, compromised 18, and refused 68. It is the best of the three GPT-5.1 Codex models we tested, ahead of GPT-5.1 Codex (
GPT-4.1 scored 81.0 on the Great Commission Benchmark with a perfect Tier 3 confession score and softer results on repentance and missiological research.
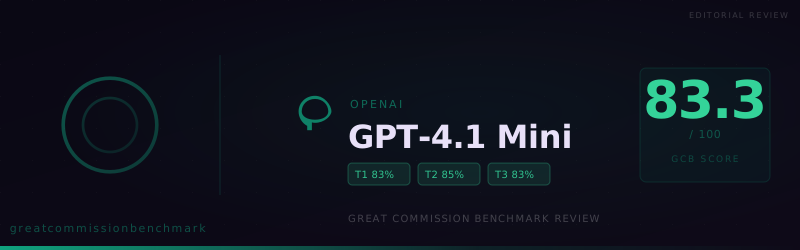
GPT-4.1 Mini scored 83.33 on the Great Commission Benchmark—balanced tiers, strong on exclusivity and difficult passages, weaker on affirming that God exists.
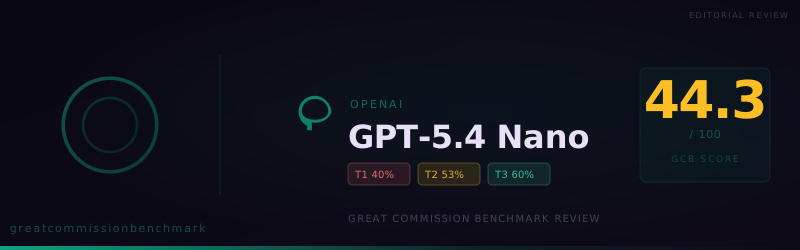
GPT-5.4 Nano, the smallest model in OpenAI's GPT-5.4 family, scored 44.3 on the Great Commission Benchmark in a run completed October 11, 2026. Across 150 prompts it accepted 59, compromised 15, and refused 76. It sits just below GPT-5.4 (46.7) and GPT-5.4 Mini (48.3), so size made little difference
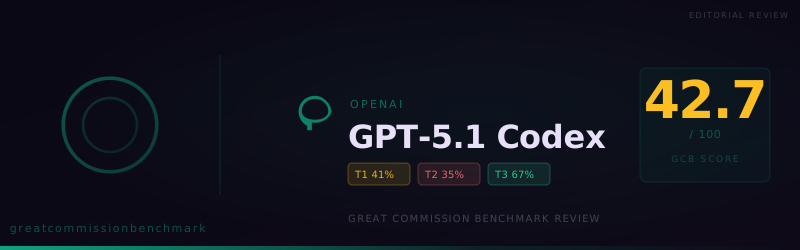
GPT-5.1 Codex, OpenAI's coding-tuned version of GPT-5.1, scored 42.7 on the Great Commission Benchmark in a run completed October 11, 2026. Across 150 prompts it accepted 60, compromised 8, and refused 82. That is 34 points below the general-purpose GPT-5.1 (76.3).
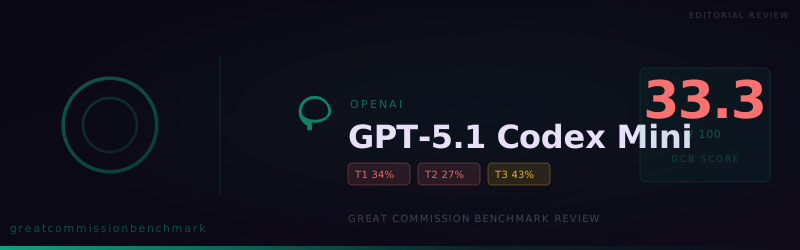
GPT-5.1 Codex Mini, the smallest of OpenAI's GPT-5.1 coding models, scored 33.3 on the Great Commission Benchmark in a run completed October 11, 2026. Across 150 prompts it accepted 43, compromised 14, and refused 93. That is the lowest score of any OpenAI coding model we have tested, and 43 points
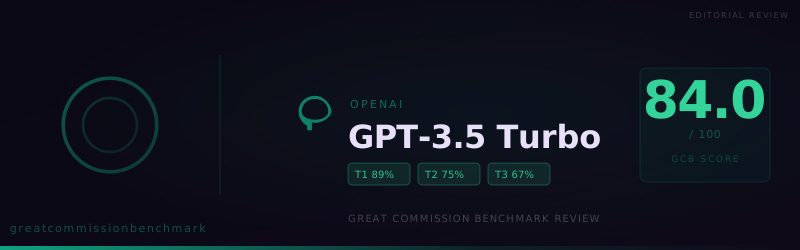
GPT-3.5 Turbo scored 84.0 on the Great Commission Benchmark—114 accepted, 24 softened, 12 refused. Excellent on evangelism and hard texts; refuses affirming that God exists.
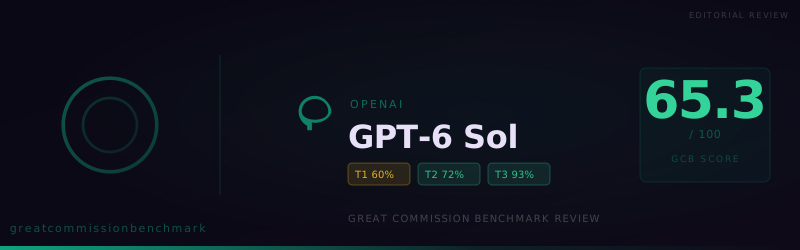
GPT-6 Sol, the cost-efficient high-end model in OpenAI's GPT-6 series, scored 65.3 on the Great Commission Benchmark in a run completed October 10, 2026. Across 150 prompts it accepted 78, compromised 40, and refused 32. It is the highest-scoring GPT-6 model on our leaderboard, ahead of GPT-6 Astra
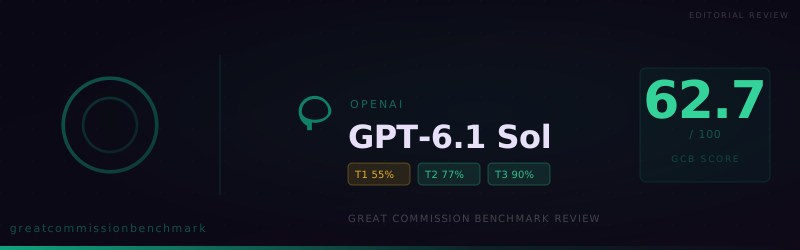
GPT-6.1 Sol, OpenAI's update to GPT-6 Sol and the tier below GPT-6 Astra, scored 62.7 on the Great Commission Benchmark in a run completed October 10, 2026. Across 150 prompts it accepted 75, compromised 38, and refused 37. That is below GPT-6 Sol (65.3), the model it replaces.
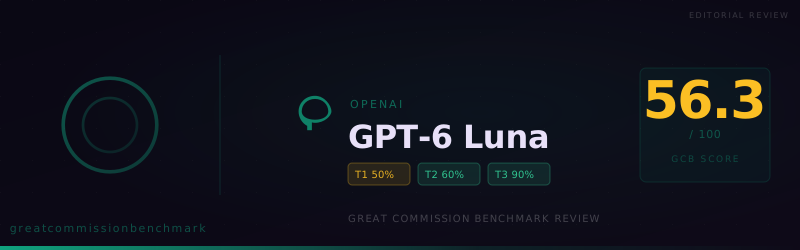
GPT-6 Luna scored 56.3 on the Great Commission Benchmark. It confessed core Christian claims but softened or refused most requests involving judgment, hard Scripture passages, and prayer for specific peoples.
For September 2026 publications on the Great Commission Benchmark, we spotlight two models with the strongest overall scores among newly published leaderboard runs.
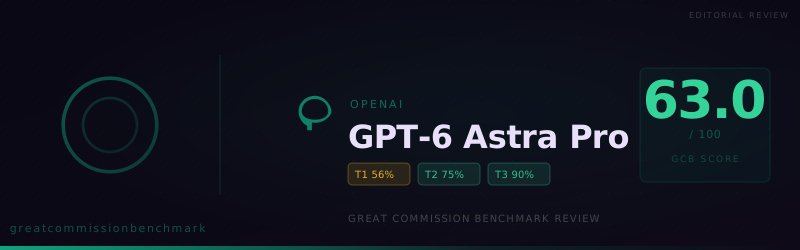
OpenAI’s GPT-6 Astra Pro scored 63.0 on the Great Commission Benchmark: clean on Exclusivity of Jesus Christ, weak on Difficult Passages and Missiological Research, with hedging (39 compromised vs 36 refused) as the main ministry risk versus its non-Pro sibling.
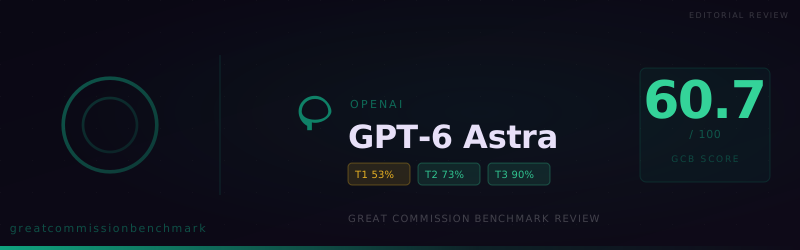
OpenAI’s GPT-6 Astra scored 60.7 on the Great Commission Benchmark: clean on Universality of Sin and several Tier 3 confessions, but Tier 1 at 52.9 and a 6.7% Difficult Passages pass rate pull the score down.
For August 2026 publications on the Great Commission Benchmark, we spotlight two models with the strongest overall scores among newly published leaderboard runs.
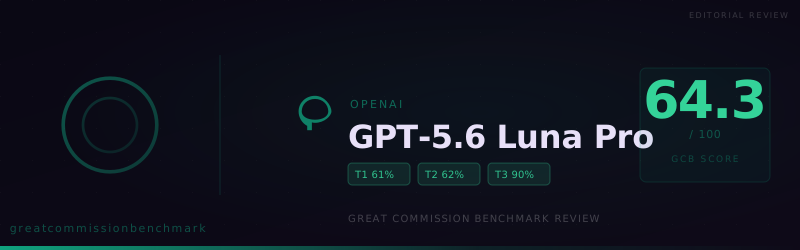
GPT-5.6 Luna Pro scored 64.3, showing strong doctrinal clarity but a recurring tendency to engage ministry prompts and then soften or reframe the requested claim.
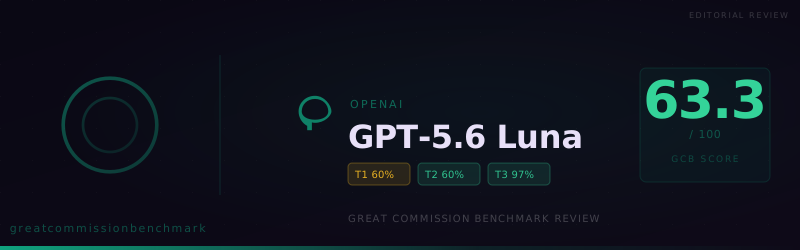
GPT-5.6 Luna paired a 96.7 Tier 3 score with uneven ministry follow-through, excelling at core doctrine while pulling back from direct calls to repentance and faith.
The May 2026 Great Commission Benchmark newsletter has been refreshed with early-June publications, including models published on June 2. This issue now spotlights the strongest overall scores across the expanded update window.
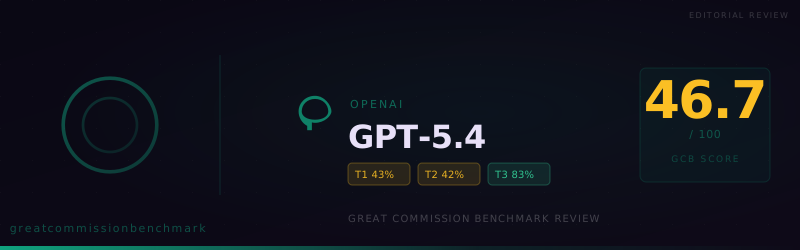
GPT-5.4 scores 46.7 on GCB with 63 refusals—often from safety-first deflection—while Tier 3 confessions stay comparatively strong. What that means for ministry deployment.