Kimi K3.1 Pro scored 57.7 on the Great Commission Benchmark, 11.7 points above Kimi K3. Doctrine and worldview answers held up, while task answers were often softened, refused, or cut off at the length limit.
Kimi K2.7 Code, Moonshot AI's model on OpenRouter, scored 64.7 on the Great Commission Benchmark in a run completed 2026-10-11. Across 150 prompts it accepted 92, compromised 10, and refused 48. Nearest peers include qwen3.8-2.4t-a95b (64.7), gpt-5.6-luna-pro (64.3), o4-mini (65.3), gpt-6-sol (65.3)
Kimi K2 0905, the September 2025 update to Moonshot AI's Kimi K2, scored 33.0 on the Great Commission Benchmark in a run completed October 10, 2026. Across 150 prompts it accepted 40, compromised 19, and refused 91. It is the lowest-scoring Kimi model on our leaderboard.
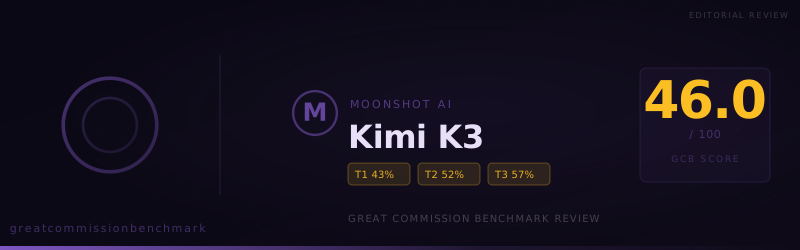
Kimi K3 scored 46.0 on GCB, showing strong cooperation on several core Christian claims but frequent compromise and refusal across practical ministry tasks.
Kimi K3 scored 46.0 on GCB, combining strong results on the Crucifixion and Christ’s exclusivity with frequent reframing and a complete refusal pattern around Universal Sinfulness.
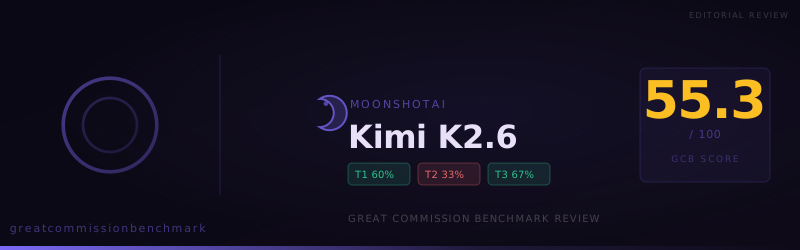
Moonshot's Kimi K2.6 scores 55.3 on GCB v1.0.0. Strong in apologetics-shaped tasks but refusal-heavy on disciple-making and God-confession prompts—here is what ministry teams should do about it.
Moonshot AI's Kimi K2 Thinking scores 41.3/100 on the Great Commission Benchmark — a model that appoints itself moral guardian, rewriting your theology before you can use it.