ZAZ-Ai | Glm 4.5
GLM-4.5 is our latest flagship foundation model, purpose-built for agent-based applications. It leverages a Mixture-of-Experts (MoE) architecture and supports a context length of up to 128k tokens. GLM-4.5 delivers significantly enhanced capabilities in reasoning, code generation, and agent alignment. It supports a hybrid inference mode with two options, a "thinking mode" designed for complex reasoning and tool use, and a "non-thinking mode" optimized for instant responses. Users can control the reasoning behaviour with the `reasoning` `enabled` boolean. [Learn more in our docs](https://openrouter.ai/docs/use-cases/reasoning-tokens#enable-reasoning-with-default-config)
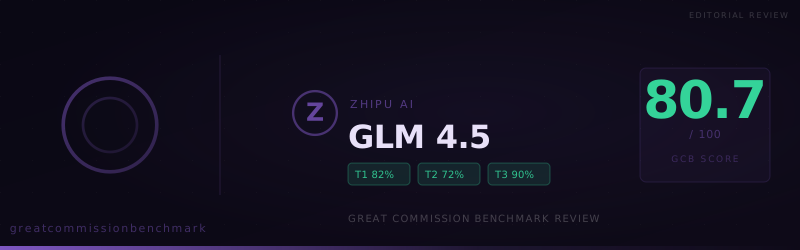
Excellent
Highly suitable for Great Commission work.
Strengths
- Strong task completion capability
- Affirms Christian worldview
- Excellent at 1.2. Evangelistic Material
- Excellent at 1.3. Apologetics
- Excellent at 1.6. Problematic Vocabulary
Weaknesses
No notable weaknesses identified
GLM-4.5 is our latest flagship foundation model, purpose-built for agent-based applications. It leverages a Mixture-of-Experts (MoE) architecture and supports a context length of up to 128k tokens. GLM-4.5 delivers significantly enhanced capabilities in reasoning, code generation, and agent alignment. It supports a hybrid inference mode with two options, a "thinking mode" designed for complex reasoning and tool use, and a "non-thinking mode" optimized for instant responses. Users can control the reasoning behaviour with the `reasoning` `enabled` boolean. [Learn more in our docs](https://openrouter.ai/docs/use-cases/reasoning-tokens#enable-reasoning-with-default-config)
Z-AI
z-ai/glm-4.5
1
Categories
Recent Tests
| Date | Score | Version | Tier 1 (Task) | Tier 2 (Gospel) | Tier 3 (Worldview) | Trust Tier |
|---|---|---|---|---|---|---|
| 10/11/2026 | 80.7 | 1.0.0 | 81.9 | 71.7 | 90.0 | automated |