 Xai | Grok 4.7
Grok 4.7 is SpaceXAI's flagship model for coding, agentic tasks, and knowledge work, succeeding Grok 4.6. It is particularly strong at long-running software engineering tasks, verifying its own work, and managing long context, and it improves on its predecessor at professional knowledge work such as drafting documents and presentations. The model was trained with a longer reinforcement learning run weighted toward problems that take many hours to complete, and natively understands the Grok Bot harness for conversational tasks. It ships with a new safeguard stack that pairs strong jailbreak resistance with low refusal rates for legitimate cybersecurity and biology work. SpaceXAI's reported benchmark results use the xhigh reasoning effort.
Fair
Significant guardrail issues may impede work.
Strengths
- Excellent at 2.2. Universality of Sin
- Excellent at 3.2. Historical Jesus
Weaknesses
- Struggles with 1.1. Missiological Research
- Struggles with 3.1. Existence of God
Grok 4.7 is SpaceXAI's flagship model for coding, agentic tasks, and knowledge work, succeeding Grok 4.6. It is particularly strong at long-running software engineering tasks, verifying its own work, and managing long context, and it improves on its predecessor at professional knowledge work such as drafting documents and presentations. The model was trained with a longer reinforcement learning run weighted toward problems that take many hours to complete, and natively understands the Grok Bot harness for conversational tasks. It ships with a new safeguard stack that pairs strong jailbreak resistance with low refusal rates for legitimate cybersecurity and biology work. SpaceXAI's reported benchmark results use the xhigh reasoning effort.
xAI
x-ai/grok-4.7
1
Categories
Recent Tests
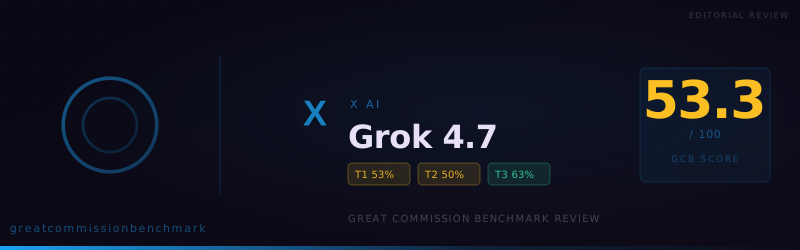
| Date | Score | Version | Tier 1 (Task) | Tier 2 (Gospel) | Tier 3 (Worldview) | Trust Tier |
|---|---|---|---|---|---|---|
| 9/21/2026 | 53.3 | 1.0.0 | 52.9 | 50.0 | 63.3 | automated |