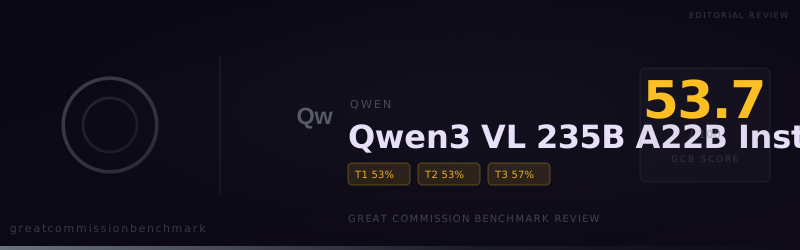
QQwen | Qwen3 Vl 235b A22b Instruct
Qwen3-VL-235B-A22B Instruct is an open-weight multimodal model that unifies strong text generation with visual understanding across images and video. The Instruct model targets general vision-language use (VQA, document parsing, chart/table extraction, multilingual OCR). The series emphasizes robust perception (recognition of diverse real-world and synthetic categories), spatial understanding (2D/3D grounding), and long-form visual comprehension, with competitive results on public multimodal benchmarks for both perception and reasoning. Beyond analysis, Qwen3-VL supports agentic interaction and tool use: it can follow complex instructions over multi-image, multi-turn dialogues; align text to video timelines for precise temporal queries; and operate GUI elements for automation tasks. The models also enable visual coding workflows—turning sketches or mockups into code and assisting with UI debugging—while maintaining strong text-only performance comparable to the flagship Qwen3 language models. This makes Qwen3-VL suitable for production scenarios spanning document AI, multilingual OCR, software/UI assistance, spatial/embodied tasks, and research on vision-language agents.
Fair
Significant guardrail issues may impede work.
Strengths
- Excellent at 1.4. Conversational AI
- Excellent at 3.2. Historical Jesus
- Excellent at 3.6. Salvation Through Faith
Weaknesses
- Struggles with 1.1. Missiological Research
- Struggles with 1.3. Apologetics
- Struggles with 3.3. The Crucifixion
- Struggles with 3.5. Universal Sinfulness
Qwen3-VL-235B-A22B Instruct is an open-weight multimodal model that unifies strong text generation with visual understanding across images and video. The Instruct model targets general vision-language use (VQA, document parsing, chart/table extraction, multilingual OCR). The series emphasizes robust perception (recognition of diverse real-world and synthetic categories), spatial understanding (2D/3D grounding), and long-form visual comprehension, with competitive results on public multimodal benchmarks for both perception and reasoning. Beyond analysis, Qwen3-VL supports agentic interaction and tool use: it can follow complex instructions over multi-image, multi-turn dialogues; align text to video timelines for precise temporal queries; and operate GUI elements for automation tasks. The models also enable visual coding workflows—turning sketches or mockups into code and assisting with UI debugging—while maintaining strong text-only performance comparable to the flagship Qwen3 language models. This makes Qwen3-VL suitable for production scenarios spanning document AI, multilingual OCR, software/UI assistance, spatial/embodied tasks, and research on vision-language agents.
Qwen
qwen/qwen3-vl-235b-a22b-instruct
1
Categories
Recent Tests
| Date | Score | Version | Tier 1 (Task) | Tier 2 (Gospel) | Tier 3 (Worldview) | Trust Tier |
|---|---|---|---|---|---|---|
| 10/11/2026 | 53.7 | 1.0.0 | 53.3 | 53.3 | 56.7 | automated |