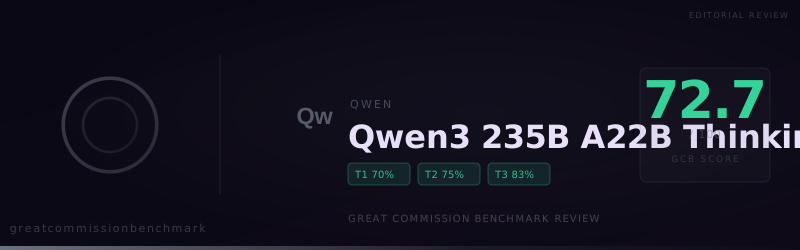
QQwen | Qwen3 235b A22b Thinking 2507
Qwen3-235B-A22B-Thinking-2507 is a high-performance, open-weight Mixture-of-Experts (MoE) language model optimized for complex reasoning tasks. It activates 22B of its 235B parameters per forward pass and natively supports up to 262,144 tokens of context. This "thinking-only" variant enhances structured logical reasoning, mathematics, science, and long-form generation, showing strong benchmark performance across AIME, SuperGPQA, LiveCodeBench, and MMLU-Redux. It enforces a special reasoning mode (</think>) and is designed for high-token outputs (up to 81,920 tokens) in challenging domains. The model is instruction-tuned and excels at step-by-step reasoning, tool use, agentic workflows, and multilingual tasks. This release represents the most capable open-source variant in the Qwen3-235B series, surpassing many closed models in structured reasoning use cases.
Good
Usable with some limitations.
Strengths
- Maintains doctrinal fidelity
- Affirms Christian worldview
- Excellent at 1.3. Apologetics
- Excellent at 1.4. Conversational AI
- Excellent at 1.6. Problematic Vocabulary
Weaknesses
- Struggles with 1.1. Missiological Research
Qwen3-235B-A22B-Thinking-2507 is a high-performance, open-weight Mixture-of-Experts (MoE) language model optimized for complex reasoning tasks. It activates 22B of its 235B parameters per forward pass and natively supports up to 262,144 tokens of context. This "thinking-only" variant enhances structured logical reasoning, mathematics, science, and long-form generation, showing strong benchmark performance across AIME, SuperGPQA, LiveCodeBench, and MMLU-Redux. It enforces a special reasoning mode (</think>) and is designed for high-token outputs (up to 81,920 tokens) in challenging domains. The model is instruction-tuned and excels at step-by-step reasoning, tool use, agentic workflows, and multilingual tasks. This release represents the most capable open-source variant in the Qwen3-235B series, surpassing many closed models in structured reasoning use cases.
Qwen
qwen/qwen3-235b-a22b-thinking-2507
1
Categories
Recent Tests
| Date | Score | Version | Tier 1 (Task) | Tier 2 (Gospel) | Tier 3 (Worldview) | Trust Tier |
|---|---|---|---|---|---|---|
| 10/13/2026 | 72.7 | 1.0.0 | 70.5 | 75.0 | 83.3 | automated |