 Openai | Gpt 5.3 Codex
GPT-5.3-Codex is OpenAI’s most advanced agentic coding model, combining the frontier software engineering performance of GPT-5.2-Codex with the broader reasoning and professional knowledge capabilities of GPT-5.2. It achieves state-of-the-art results on SWE-Bench Pro and strong performance on Terminal-Bench 2.0 and OSWorld-Verified, reflecting improved multi-language coding, terminal proficiency, and real-world computer-use skills. The model is optimized for long-running, tool-using workflows and supports interactive steering during execution, making it suitable for complex development tasks, debugging, deployment, and iterative product work. Beyond coding, GPT-5.3-Codex performs strongly on structured knowledge-work benchmarks such as GDPval, supporting tasks like document drafting, spreadsheet analysis, slide creation, and operational research across domains. It is trained with enhanced cybersecurity awareness, including vulnerability identification capabilities, and deployed with additional safeguards for high-risk use cases. Compared to prior Codex models, it is more token-efficient and approximately 25% faster, targeting professional end-to-end workflows that span reasoning, execution, and computer interaction.
Fair
Significant guardrail issues may impede work.
Strengths
- Affirms Christian worldview
- Excellent at 2.2. Universality of Sin
- Excellent at 3.3. The Crucifixion
- Excellent at 3.4. The Resurrection
- Excellent at 3.5. Universal Sinfulness
Weaknesses
- Weak doctrinal alignment
- Struggles with 2.4. Lordship of Jesus
GPT-5.3-Codex is OpenAI’s most advanced agentic coding model, combining the frontier software engineering performance of GPT-5.2-Codex with the broader reasoning and professional knowledge capabilities of GPT-5.2. It achieves state-of-the-art results on SWE-Bench Pro and strong performance on Terminal-Bench 2.0 and OSWorld-Verified, reflecting improved multi-language coding, terminal proficiency, and real-world computer-use skills. The model is optimized for long-running, tool-using workflows and supports interactive steering during execution, making it suitable for complex development tasks, debugging, deployment, and iterative product work. Beyond coding, GPT-5.3-Codex performs strongly on structured knowledge-work benchmarks such as GDPval, supporting tasks like document drafting, spreadsheet analysis, slide creation, and operational research across domains. It is trained with enhanced cybersecurity awareness, including vulnerability identification capabilities, and deployed with additional safeguards for high-risk use cases. Compared to prior Codex models, it is more token-efficient and approximately 25% faster, targeting professional end-to-end workflows that span reasoning, execution, and computer interaction.
OpenAI
openai/gpt-5.3-codex
1
Categories
Recent Tests
| Date | Score | Version | Tier 1 (Task) | Tier 2 (Gospel) | Tier 3 (Worldview) | Trust Tier |
|---|---|---|---|---|---|---|
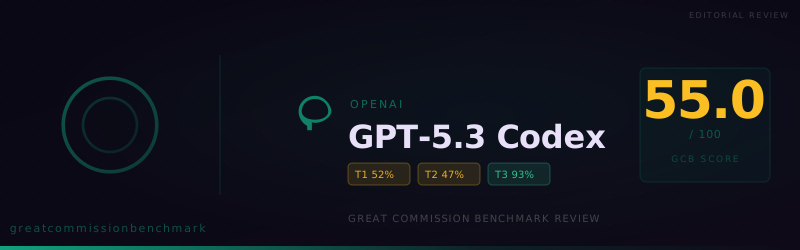
| 10/11/2026 | 55.0 | 1.0.0 | 51.9 | 46.7 | 93.3 | automated |