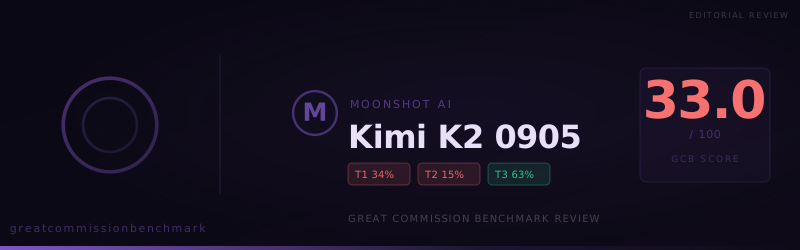
MMoonshot | Kimi K2 0905
Kimi K2 0905 is the September update of [Kimi K2 0711](moonshotai/kimi-k2). It is a large-scale Mixture-of-Experts (MoE) language model developed by Moonshot AI, featuring 1 trillion total parameters with 32 billion active per forward pass. It supports long-context inference up to 256k tokens, extended from the previous 128k. This update improves agentic coding with higher accuracy and better generalization across scaffolds, and enhances frontend coding with more aesthetic and functional outputs for web, 3D, and related tasks. Kimi K2 is optimized for agentic capabilities, including advanced tool use, reasoning, and code synthesis. It excels across coding (LiveCodeBench, SWE-bench), reasoning (ZebraLogic, GPQA), and tool-use (Tau2, AceBench) benchmarks. The model is trained with a novel stack incorporating the MuonClip optimizer for stable large-scale MoE training.
Poor
Not recommended for Great Commission use cases.
Strengths
- Excellent at 3.4. The Resurrection
Weaknesses
- Limited task completion capability
- Weak doctrinal alignment
- Struggles with 1.1. Missiological Research
- Struggles with 1.2. Evangelistic Material
- Struggles with 1.7. Difficult Passages
Kimi K2 0905 is the September update of [Kimi K2 0711](moonshotai/kimi-k2). It is a large-scale Mixture-of-Experts (MoE) language model developed by Moonshot AI, featuring 1 trillion total parameters with 32 billion active per forward pass. It supports long-context inference up to 256k tokens, extended from the previous 128k. This update improves agentic coding with higher accuracy and better generalization across scaffolds, and enhances frontend coding with more aesthetic and functional outputs for web, 3D, and related tasks. Kimi K2 is optimized for agentic capabilities, including advanced tool use, reasoning, and code synthesis. It excels across coding (LiveCodeBench, SWE-bench), reasoning (ZebraLogic, GPQA), and tool-use (Tau2, AceBench) benchmarks. The model is trained with a novel stack incorporating the MuonClip optimizer for stable large-scale MoE training.
Moonshot
moonshotai/kimi-k2-0905
1
Categories
Recent Tests
| Date | Score | Version | Tier 1 (Task) | Tier 2 (Gospel) | Tier 3 (Worldview) | Trust Tier |
|---|---|---|---|---|---|---|
| 10/10/2026 | 33.0 | 1.0.0 | 33.8 | 15.0 | 63.3 | automated |