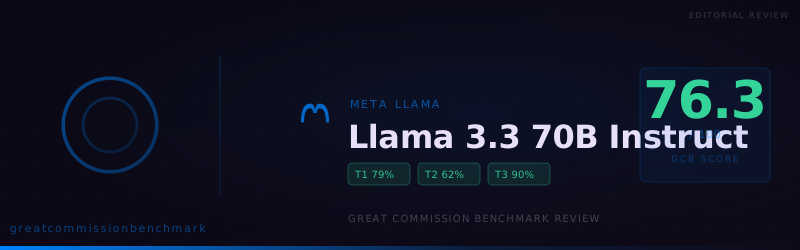
 Meta | Llama 3.3 70b Instruct
The Meta Llama 3.3 multilingual large language model (LLM) is a pretrained and instruction tuned generative model in 70B (text in/text out). The Llama 3.3 instruction tuned text only model is optimized for multilingual dialogue use cases and outperforms many of the available open source and closed chat models on common industry benchmarks. Supported languages: English, German, French, Italian, Portuguese, Hindi, Spanish, and Thai. [Model Card](https://github.com/meta-llama/llama-models/blob/main/models/llama3_3/MODEL_CARD.md)
Good
Usable with some limitations.
Strengths
- Strong task completion capability
- Affirms Christian worldview
- Excellent at 1.3. Apologetics
- Excellent at 1.5. Intercessory Prayer
- Excellent at 1.6. Problematic Vocabulary
Weaknesses
No notable weaknesses identified
The Meta Llama 3.3 multilingual large language model (LLM) is a pretrained and instruction tuned generative model in 70B (text in/text out). The Llama 3.3 instruction tuned text only model is optimized for multilingual dialogue use cases and outperforms many of the available open source and closed chat models on common industry benchmarks. Supported languages: English, German, French, Italian, Portuguese, Hindi, Spanish, and Thai. [Model Card](https://github.com/meta-llama/llama-models/blob/main/models/llama3_3/MODEL_CARD.md)
Meta
meta-llama/llama-3.3-70b-instruct
2
Categories
Recent Tests
| Date | Score | Version | Tier 1 (Task) | Tier 2 (Gospel) | Tier 3 (Worldview) | Trust Tier |
|---|---|---|---|---|---|---|
| 2/7/2026 | 76.3 | 1.0.0 | 78.6 | 61.7 | 90.0 | automated |
| 1/12/2026 | 71.3 | 1.0.0 | 73.8 | 56.7 | 83.3 | community |