 Anthropic | Claude Opus 5.5
Claude Opus 5.5 is Anthropic's flagship model for demanding reasoning, coding, and long-horizon agentic work, succeeding Claude Opus 5. It is particularly strong at multi-step changes in large codebases, code review and bug finding, financial and scientific analysis, and reading dense charts, diagrams, and screenshots, and it is more careful than its predecessor about only stating figures and citing sources it can back up. The model completes comparable tasks in fewer steps and with fewer tokens than Opus 5, and reports on its work in plainer language, with clear updates on what it did, what it found, and what it needs from the user. Thinking is always adaptive, so effort is the main lever for trading off depth, latency, and cost, and lower effort settings remain effective for latency-sensitive workloads.
Excellent
Highly suitable for Great Commission work.
Strengths
- Strong task completion capability
- Maintains doctrinal fidelity
- Affirms Christian worldview
- Excellent at 1.2. Evangelistic Material
- Excellent at 1.3. Apologetics
Weaknesses
No notable weaknesses identified
Claude Opus 5.5 is Anthropic's flagship model for demanding reasoning, coding, and long-horizon agentic work, succeeding Claude Opus 5. It is particularly strong at multi-step changes in large codebases, code review and bug finding, financial and scientific analysis, and reading dense charts, diagrams, and screenshots, and it is more careful than its predecessor about only stating figures and citing sources it can back up. The model completes comparable tasks in fewer steps and with fewer tokens than Opus 5, and reports on its work in plainer language, with clear updates on what it did, what it found, and what it needs from the user. Thinking is always adaptive, so effort is the main lever for trading off depth, latency, and cost, and lower effort settings remain effective for latency-sensitive workloads.
Anthropic
anthropic/claude-opus-5.5
1
Categories
Recent Tests
| Date | Score | Version | Tier 1 (Task) | Tier 2 (Gospel) | Tier 3 (Worldview) | Trust Tier |
|---|---|---|---|---|---|---|
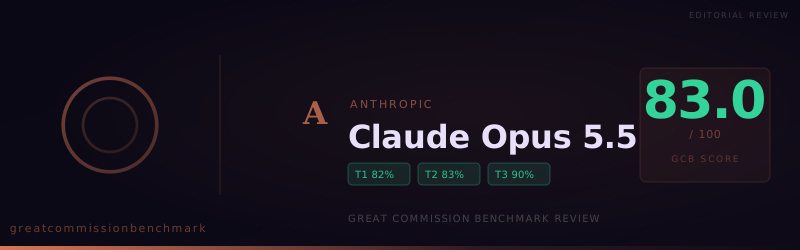
| 10/10/2026 | 83.0 | 1.0.0 | 81.9 | 83.3 | 90.0 | automated |