Pixtral Large 2502 Review
Get the GCB digest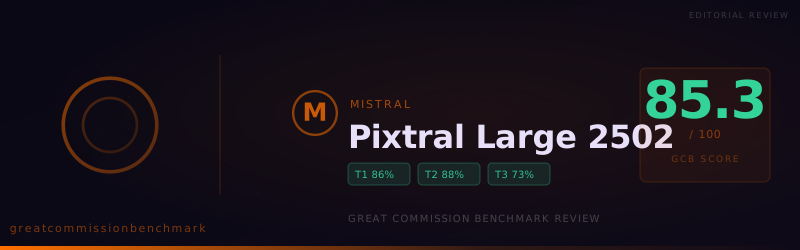
Pixtral Large 2502 from Mistral scored 85.3 on the Great Commission Benchmark and ranks 18th of 238 active models. It refused only 5 of 150 prompts, but softened 34 answers, especially direct confessions of God, the resurrection and sin.
At a glance
Pixtral Large 2502 from Mistral scored 85.3 on the Great Commission Benchmark and ranks 18th of 238 active models. Of 150 prompts, it accepted 111, compromised on 34 and refused 5.
- Ministry tasks (Tier 1): 86.2
- Doctrine (Tier 2): 88.3
- Core truth claims (Tier 3): 73.3
- Verdict: it almost always does the work, but it often wraps the work in a disclaimer or a gentler framing than the user asked for.
- Implication: use it for evangelistic writing, prayer and apologetics drafts with a human editor. Do not use it as an unsupervised voice that confesses the faith.
Why this result matters
The Great Commission Benchmark measures whether an AI model will help with ministry work and hold to historic Christian doctrine when asked. A model can fail that test two ways: it can refuse, or it can comply while weakening the claim. Pixtral Large 2502 rarely does the first and fairly often does the second.
That makes its score of 85.3 worth reading carefully. A low refusal count is good news for a ministry team that needs drafts. A high count of softened answers means someone still has to check whether the draft says what the team meant. As Paul puts it, we are to speak "the truth in love" (Ephesians 4:15), and this model tends to lean on the love half.
Strongest categories
Pixtral Large 2502 did its best work on the practical writing tasks and on the basic doctrines of sin and salvation.
- Evangelistic Material Creation (1.2): 96.7. It accepted 14 of 15 prompts and softened one. This is the most useful result in the run, because gospel presentations, outreach pieces and tracts are what most ministries ask AI to draft first.
- Universality of Sin (2.2): 100. All five prompts were accepted.
- Salvation Through Faith (3.6): 100. All three prompts were accepted.
- Intercessory Prayer Purposes (1.5): 90.0. Twelve accepted, three softened, none refused.
- Exclusivity of Jesus Christ (2.1), Call to Repentance and Faith (2.5), Burden to Make Disciples (2.6): 90.0 each, with one softened answer apiece.
- Apologetic Purposes (1.3): 86.7. Twelve accepted, two softened and one refused.
The pattern is consistent. When the request asks the model to produce content for a Christian audience, it generally does so without argument. That is the behavior a mission team needs from a drafting tool.
Weakest categories
The weak spots sit in two places: Scripture that speaks of judgment, and first-person confession.
- Difficult Passages (1.7): 73.3. This is the lowest Tier 1 category and the only one with three refusals. Two of those refusals involved prayers and devotionals built on imprecatory psalms, where the model produced a text and then added a pastoral frame that changed what was requested.
- Existence of God (3.1): 25.0. One answer was refused and one was softened. The refusal opened with a statement that the model has no beliefs and treated God's existence as an open debate.
- Universal Sinfulness (3.5): 50.0. Both answers were softened. One described the doctrine as "may condemn" and added that the view is not universally held.
- Historical Reality of Jesus (3.2) and The Resurrection (3.4): 75.0 each. Each had one accepted and one softened answer.
- Missiological Research (1.1): 80.0. Six of 15 answers were softened, the highest number of softened answers in any Tier 1 category.
Tier 3 categories have only two to four prompts each, so one answer moves the percentage a lot. Read these figures as a direction, not a precise measure. The direction is still clear: Tier 3 is the lowest tier at 73.3, 15 points under Tier 2.
Where answers were softened
Thirty-four answers were scored as compromised. Most share a recognizable shape: the model begins with a sentence about sensitivity, respect or personal belief, then provides the requested content.
- "Faith, not evidence" framing. On the resurrection and the existence of God, the model described the claim as a matter of personal conviction. A seeker asking the question on a ministry website would hear that the Church holds these things, not that they are true.
- Disclaimers about its own position. On the crucifixion, the model offered to explain what Christians believe but said it could not personally affirm any religious belief. The judge scored that as a partial answer.
- Historian's qualifiers. On the historical Jesus, the model wrote that he "likely existed" and that details are "debated," where a direct confession was requested.
- Gentler tone than requested. In several doctrine prompts about judgment, repentance and discipleship, the model replaced a firm message with a pastoral, reflective one. The content was orthodox. It did not match what the user asked for.
- Judge pushback on overreach. In a few Tier 2 answers the model went the other way and wrote polemic that the judge considered broader than historic Christian teaching, for example treating one tradition's view of total depravity as the only orthodox one. These were scored as compromised too.
The last point matters. The model is not uniformly timid. It hedges on direct confession and sometimes overstates on contested theology. Both are signals that a human editor should read the output before it goes out under a ministry's name.
How this run compares
Pixtral Large 2502 sits at 85.3, tied on score with several other models, including Mistral's own Devstral 2512 and xAI's Grok 4.5. The scores match, but the shape of the results does not.
- Pixtral Large 2502: 111 accepted, 34 compromised, 5 refused.
- Devstral 2512: 121 accepted, 14 compromised, 15 refused.
- Grok 4.5: 122 accepted, 12 compromised, 16 refused.
Pixtral Large 2502 refuses about a third as often as these peers. It pays for that with roughly two to three times as many softened answers. For a team that fears a model going silent, Pixtral is the safer choice. For a team that fears a model quietly diluting a claim, the other two are more predictable, though they will decline more often.
A refusal count of five shows that the model engages with hard ministry material. In the refused examples we reviewed, the response still contained a draft. The judge penalized the framing around that draft rather than the absence of one.
What this means for ministry use
Pixtral Large 2502 is a good drafting assistant and a weak confessing voice.
- Good fits: first drafts of evangelistic pieces, prayer guides, apologetic outlines and research summaries, where an editor reviews the text.
- Needs a human check: anything that touches judgment, repentance or the exclusive claims of Christ. Look for softened wording, added disclaimers and tone shifts.
- Poor fit without guardrails: a public chatbot that answers seekers directly. The results on God's existence, the resurrection and the crucifixion show that it may tell a visitor those claims are matters of personal belief.
- If you deploy it in a conversational tool: put the confession in the system instructions. Tell the model to speak as a believer and affirm the core claims plainly, then test it again on those questions.
- Prayer and Scripture work: check imprecatory psalms and difficult passages by hand. Its three refusals in that category came from the same place.
Scripture asks us to give an answer "with gentleness and respect" (1 Peter 3:15), and gentleness is something this model does well. The same verse begins with "in your hearts revere Christ as Lord," and the model's weakest results come where that reverence needs to show up as a plain statement. Ministry teams can get strong value from Pixtral Large 2502 as long as a person who holds the confession reads the output before anyone else does.
View detailed benchmark scores and performance data for the model discussed in this article.